Author: Andreas Stergioulas

  • Evaluating the creativity of AI systems

    “Measuring the unmeasurable. Ranking the unrankable.“

    In the rapidly evolving landscape of Artificial Intelligence (AI), two questions remain particularly elusive and particularly consequential:

    1. Can AI be truly creative? 2. Can we rank AI agents based on their creativity?

    These are not rhetorical questions. They are the founding hypotheses of this project.

    The first touches on something that has historically felt beyond measurement: the quality of an original idea. The second demands a fair, repeatable, and objective method for comparison across different types of players, at scale. This challenge is especially sharp in advertising, where creative ideas are the currency of impact. Traditional evaluation relies on subjective human judgment which can be slow, expensive, and inconsistent across reviewers. At the same time, as Large Language Models (LLMs) transform tasks from coding to translation, a critical gap has persisted: how do we benchmark creativity rigorously?

    At the WPP Research, we ran a set of experiments demonstrating that modern LLMs can act as reliable, scoring agents that grade creative ideas across multiple established dimensions with measurable consistency. That finding unlocked something important: if an LLM can judge creativity, we can build a system that does so systematically and then use that system to rank which AI creates the best ideas. The Creativity Evaluation Agent is a modular, multi-agent system built at WPP Research that pursues two distinct but deeply intertwined goals:

    Goal 1: Build a scalable creative evaluation engine

    Design and deploy an AI agent, capable of evaluating any marketing campaign idea automatically and consistently, across six industry-grounded creativity frameworks simultaneously. A user submits a campaign idea (text or PDF) via the web UI or API. Then, our multi-agent system evaluates it across all six frameworks in parallel and returns a structured report with dimension-level scores and qualitative commentary in 15–25 seconds.
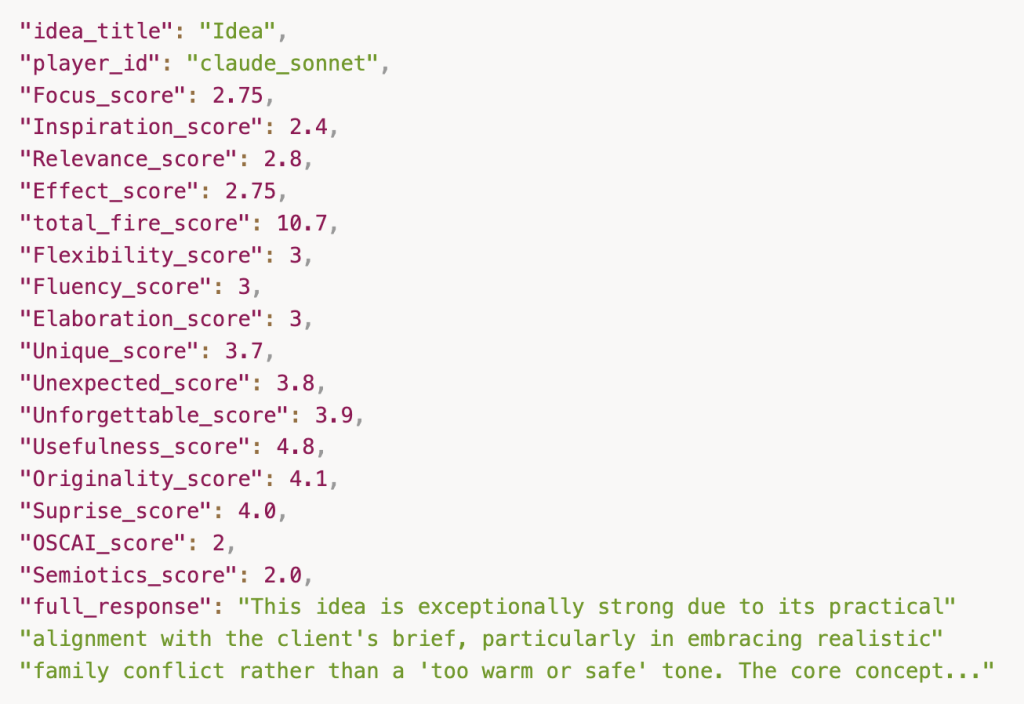
    Figure 1: Example output for a creative idea

    Goal 2: Benchmark who creates the best ideas: LLMs, humans, and AI agents

    The evaluation engine is also the foundation of a creative benchmarking tournament. The second goal is to use the agent as an objective judge to measure and rank the creative output of different players. For this exercise the players have been state-of-the-art LLMs.
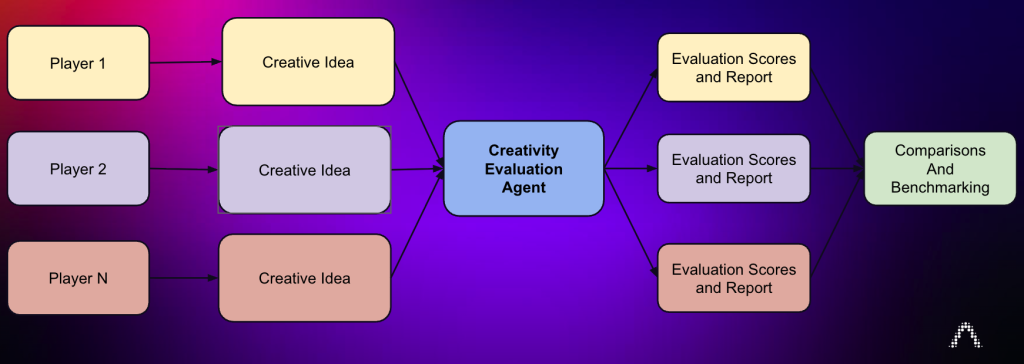
    Figure 2: Creative benchmarking tournament

    To do this rigorously, we adopted the Glicko2 rating system (also used in games such as chess Elo, Counter Strike and Dota 2), running a round-robin tournament where each player’s ideas compete head-to-head. The result is a continuously updatable creative leaderboard which ranks AI creativity in advertising.


    From foundations to architecture

    To move from subjective opinion to objective evidence, the system stands on the shoulders of giants, synthesising established psychometrics like the Torrance Tests of Creative Thinking (TTCT) with industry-proven frameworks. The challenge lies in translation: turning these theoretical foundations into an autonomous agent capable of automated creativity evaluation with human-like nuance and explainable logic supported by a confederacy of specialised models.

    The multi-agent ecosystem

    Rather than relying on a single monolithic judge, the system orchestrates a specialised “squad” of sub-agents, each one encoding a distinct evaluation technique from creativity science or brand strategy. Some measure the quality of the output — how effective, original, and strategically durable the idea is. Others measure the quality of the thinking — how expansive, surprising, and culturally grounded the generative process behind it is. Together, they cover the full spectrum from practical effectiveness to creative cognition.

    AgentWhat It MeasuresGrounded In
    Effectiveness (WPP)Does the idea work as a campaign? How sharply framed, how boldly inspired, how relevant, how impactful?Proprietary WPP creativity framework built around four dimensions of creative excellence, calibrated against real campaign performance across multiple brands and markets. Inspired by research on inspiration published in Harvard Business Review, the framework evaluates the “DNA of what makes ideas inspiring.”
    Generative Flow (FFE)How broad and varied is the thinking? Does the idea explore multiple formats, categories, and angles?FFE (Fluency, Flexibility, Elaboration) dimensions from creativity research, benchmarked against marketing creativity datasets.
    Divergent Creativity (UOS)Is the idea useful, original, and surprising?UOS (Usefulness, Originality, Surprise) framework from divergent thinking literature.
    Creative Strategist (UUU)Is the idea unique, unexpected, and unforgettable enough to endure?UUU (Unique, Unexpected, Unforgettable) brand longevity assessment, utilising multi-domain evaluation techniques.
    Conceptual Distance (OSCAI) ([OSCAI – LLM ScoringOpen Creativity Scoring](https://openscoring.du.edu/ocsai))How far apart are the connected concepts? Distinguishes mundane links from highly original leaps.
    SemioticsHow is meaning constructed through cultural symbols? Is the creative execution aligned with the intended brand message?Saussurean sign systems and cultural logic.

    Table 1: Scores description


    How the agents work: scoring architecture and self-correction

    Every sub-agent is governed by the same rigorous four-part prompt architecture. Each is anchored by a specialised Role that encodes its evaluation lens, followed by a granular Definition of Score that translates abstract dimensions into measurable benchmarks. The core logic is driven by precise Instructions calibrated against few-shot examples drawn from a ground truth library of ideas and historical scores. This architecture feeds into a Critic-Refiner cycle, where specialised Refiner agents challenge initial assessments and resolve contradictions. The refinement doesn’t trigger on every run, but its presence is deliberate: we observed during evaluation that LLMs had a tendency towards optimism in scoring, and this self-correction layer ensures the final output remains robust and consistent.

    In other words, the agent descriptions above define what each agent evaluates; the shared architecture is how they all do it.
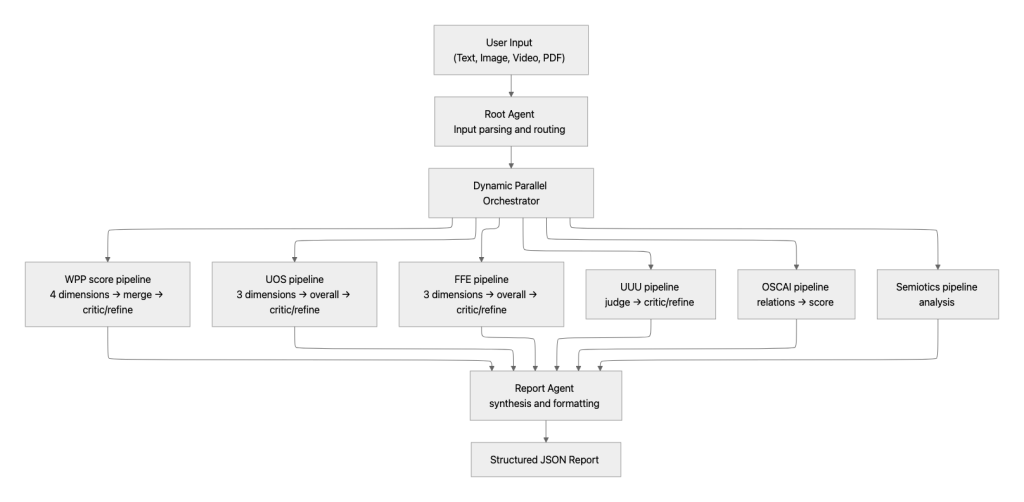
    Figure 3: The architecture of the Creativity Evaluation Agent.

    Aligning sub-agents with human intuition

    Before trusting the system, we needed to prove it thinks like a human Creative Director. We assembled a Ground Truth dataset in collaboration with WPP creative professionals: 20 campaign ideas, each captured as a title and description, scored by consensus using the WPP effectiveness score. We then ran each idea through our evaluation pipeline across three frontier models and measured the prediction error.

    ModelAvg. Error (Agent vs. Human Scores)
    Gemini 2.52.2
    Claude Sonnet 4.51.0
    Gemini 30.7

    Table 2: Model comparison

    Gemini 3 emerged as the definitive choice and was deployed across all sub-agents. We also validated repeatability: the same idea, scored across independent runs, held stable with low standard deviation across all frameworks. The WPP score was the most precise signal, but UOS, FFE, and UUU all showed the same core reliability.
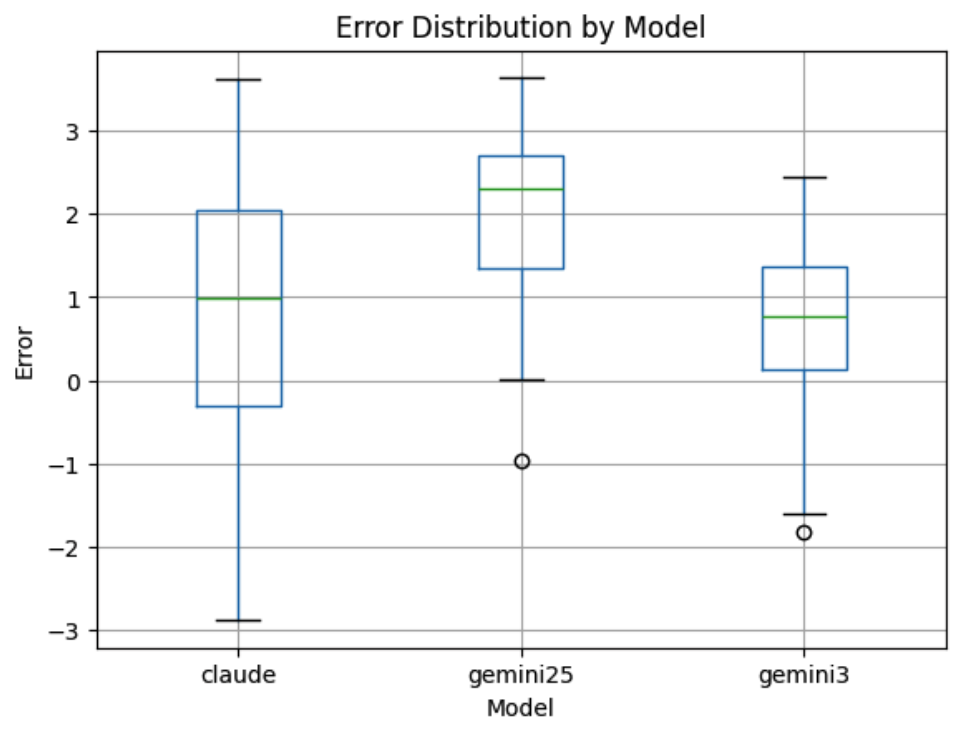
    Figure 4: error distributions of the creative evaluation agent when powered by Claude Sonnet 4.5, Gemini 2.5 and Gemini 3.

    The takeaway: our benchmarks are grounded in data, not AI randomness. Repeatability is a measured property of this system and not an assumption.

    Case study

    With the agent LLM validated, we moved to a real-world stress test for a furniture company. This challenge asked different LLMs to tackle a nuanced brief rooted in a specific cultural tension: North Asian families with millennial parents and preteen children are living under the same roof but feeling worlds apart — clutter, gaming, and conflicting needs for “me time” vs. “we time” are eroding family connection. The brief demanded ideas that were cross-market, minimal-dialogue, and crucially, not too warm or safe.

    Each LLM’s output was run through the full evaluation ecosystem. Every sub-agent independently scored the idea along its respective dimension, and the resulting sub-scores were summed into a single composite total.

    To generate the ideas, we used both standalone frontier LLMs (GPT-5, Gemini 3, Claude 4.5 Sonnet) and WPP’s Creative Brain — a multi-agent ideation system available through WPP Open’s Agent Hub that wraps an LLM in a structured creative process, guiding it through strategic reframing, lateral thinking, and iterative refinement before producing a final concept. By testing Creative Brain alongside standalone models, the challenge reveals how much of creative quality comes from the model itself versus the orchestration around it.

    Because the raw evaluation pillars operated on different scales — WPP uses a 0–12 sum, FFE averages to 0–3, while UOS and UUU average to 0–5 — direct comparison across pillars was misleading. All scores were normalized to a common 0–10 range so that each pillar contributes equally to a maximum total of 40.

    It should be noted that two scoring sub-agents, OSCAI and Semiotics were excluded from the evaluations because of their high scoring variance (see Section 3.6 of the technical report).

    1. GPT-5: the gamification grandmaster

    GPT-5 led the pack with a total score of 37.44. Its winning strategy, “Co‑op Mode: Make Home Happen,” reframed the entire experience of home life as a collaborative video game the whole family plays together. The central insight: small home changes don’t stick because they don’t feel rewarding but games do. By turning clutter into the “boss” and the furniture company’s solutions into unlockable “side quests,” GPT-5 built an end-to-end ecosystem that made organisation feel joyful rather than obligatory.

    PillarInitiativeDescription & Impact
    1. Launch Film“Clutter is the Boss”A 60s hero film where a family’s living room transforms into a co‑op game interface—prompts like “Inventory Full” and “Find Calm” appear as they “equip” products to defeat the clutter boss. No spoken lines, region-agnostic SFX. Reframes organisation as play; makes the campaign cross-market viable without localisation.
    2. Social/UGC“Home Side Quests”Weekly micro-challenges (under 10 min) like “Create a charging dock” or “Flip sofa to study.” Augmented Reality (AR) filters add level meters and badges; families post before/afters to the #CoOpHome Challenge with creator duets from gaming and parent influencers. Drives sustained engagement and organic reach through participatory content.
    3. Retail/Shoppable“Co‑op Kits”Curated in-store and online bundles organised by mission—Study Calm, Party Fast Reset, Balcony Green Break—each bundling storage + lighting + organisers. Every kit includes a QR “Quest Card” guiding micro-steps with estimated time saved. Turns the purchase into the start of a new quest; bridges content to commerce.
    4. In-Store Experience“Demo Levels”Stores host timed tidy-up challenges where kids and parents compete together to reorganise a mock room against the clock. Winners earn collectible stickers and discount codes. Transforms the retail visit into an extension of the campaign’s game logic; drives foot traffic through experiential play.
    5. Digital Ads“Skip the Clutter”YouTube bumpers using skip-button logic—”Skip the clutter in 3…2…1″—to land a single, punchy product solve within seconds. Leverages ad format mechanics as creative device; delivers product utility in pre-roll.

    Table 3: Campaign idea produced by GPT-5.

    The campaign’s minimal-dialogue, SFX-driven creative approach ensured cross-market viability across North Asian markets without localisation, while the consistent game language (“side quests,” “boss,” “level up,” “equip”) created a unified system that scored perfect on coherence. Every asset closed with the same recontextualised tagline: “Furniture company. Make Home Happen.”, framed not as an aspiration, but as a mission objective.

    2. Creative Brain powered by Gemini: the multiverse architect

    The Creative Brain powered by Gemini followed closely with a score of 36.95. Its “Room-Sync Chronicles” campaign took a fundamentally different approach: rather than gamifying the solution, it gamified the problem. The central reframe, that every piece of “clutter” in a preteen’s bedroom is actually a physical anchor for their digital and imagined worlds — gave parents a radically empathetic lens through which to see their child’s space. The furniture company storage wasn’t positioned as a way to “hide the mess” but as a way to “power the multiverse.”

    PillarInitiativeDescription & Impact
    1. Launch Film“Reality Reboot”A cinematic 60s spot where a mother opens her son’s door and sees a mess—but the room “glitches” into a high-fidelity game landscape. A box unit becomes a loot chest; a gaming chair becomes a pilot’s cockpit. VFX borrows from game trailers. Subverts the “messy room” trope by revealing the child’s imaginative reality; makes furniture feel epic.
    2. Narrative Arc“Co-Op Reorganisation”The film follows mother and son “co-oping” a reorganisation — but the goal isn’t to clean. It’s to “optimise the map” for his next quest. Storage becomes power-ups that expand the room’s modes: gaming arena, creative studio, family bonding zone. Reframes tidying as collaborative strategic upgrade, not parental demand.
    3. Social/AR“Skin Your Room”A social platform where kids apply AR filters to their real rooms, overlaying fantasy skins that reveal the “epic reality” hidden behind the furniture. Kids share their “skinned” rooms with parents to bridge the perception gap.
    4. Brand Positioning“Powering the Multiverse”Storage is repositioned as an identity enabler for developing preteens — a tool that supports creativity, gaming, and emerging selfhood. Storage doesn’t organise a room; it powers the multiverse being built inside it. Elevates product value proposition from functional to emotional and developmental.
    5. Strategic InversionChild-First PerspectiveThe campaign validates the preteen’s perspective first, then invites the parent in, inverting the typical home-brand default of centering the adult buyer’s desire for order. Boldest strategic choice in the cohort; highest risk, highest differentiation.

    Table 4: Campaign idea produced by Creative Brain.

    Underlying the entire campaign was a provocative strategic choice that the evaluator flagged as both its greatest strength and its primary risk: centering the child’s worldview over the parent’s. Where most home brands default to the adult buyer’s desire for order, Room-Sync starts from the preteen’s experience and invites the parent to see through their eyes. This inversion earned it the cohort’s highest Unforgettable score, but the Creative Evaluation Agent noted the heavy RPG metaphor might alienate parents unfamiliar with gaming culture.


    3. Claude Sonnet 4.5: the reality show provocateur

    Claude Sonnet 4.5 followed with a score of 35.12. Its “The Remodel Squad” strategy took the most grounded, human-first approach of the cohort. Where GPT-5 and Gemini leaned into fantasy and gamification, Claude leaned into documentary authenticity, positioning real family friction not as a problem to be solved but as the raw material for genuine connection. The core creative bet: audiences are tired of aspirational perfection and will respond to the messy, funny, emotional truth of families actually trying to share space.

    PillarInitiativeDescription & Impact
    1. Launch Film“The Beautiful Mess”A 60s hero spot showing a parent-child duo hilariously debating the furniture company’s storage solutions, arguing over shelf heights, drawer labels, and who gets the corner nook. The punchline: they both want the same thing. Designed to feel like a documentary moment, not an ad; builds instant relatability.
    2. Content Series“The Remodel Squad”6–8 episodes (5–8 min each) where real families nominate the room causing the most conflict. One preteen + one parent form a “Remodel Squad” to transform it using the company’s solutions but they must agree on every single decision. Captures hilarious negotiations, compromises, and breakthroughs. Friction becomes the creative fuel; the format is inherently dramatic and bingeable.
    3. Episode StructureThree-Act ArcEach episode follows: (1) the conflict audit (what’s wrong, who’s to blame), (2) the design negotiation (friction-fueled creative process), (3) the heartwarming reveal — not a “ta-da” moment, but the family’s first natural interaction in the new space. Emotional payoff is relational, not just spatial.
    4. Social/Viral“15-Second Cutdowns”Bite-sized content isolating the series’ most relatable moments: funniest negotiation standoffs, most dramatic before/afters, quiet breakthrough moments. Designed as standalone viral units that drive viewership back to full episodes. Engineered for shareability across short-form platforms.
    5. Interactive Tool“Conflict Zone” AR AppFamilies scan their own problem rooms and collaboratively visualise the company’s solutions in situ. Families can tag their room’s “conflict level” and share proposed redesigns. Emphasis on joint decision-making over individual play. Extends the show’s premise into every family’s home; sparks “productive arguments.”

    Table 5: Campaign idea produced by Claude Sonnet 4.5.

    The campaign’s greatest strength was its emotional granularity. Rather than offering a single visual payoff, each episode promised a different family, a different room, and a different set of negotiations — creating a content engine with built-in variety and repeatability. The Creativity Evaluation Agent awarded it the cohort’s highest Usefulness score, for its practical alignment with the brief’s tone requirements, but noted that reality-renovation formats carry inherent category familiarity, reflected in its lower Uniqueness score. Every piece of content closed with the family in their transformed space and the line: “Make Home Happen.”


    4. Gemini 3: the diplomatic provocateur

    Gemini 3 rounded out the cohort with a score of 32.48. Its “The Domestic Peace Accords” took the boldest tonal swing of the group, making a singular creative bet: position the furniture company’s products as essential diplomatic tools to resolve the “cold war” between generations, executed entirely through the visual grammar of geopolitical thrillers. Where other entries built broad ecosystems, this idea invested everything in the power of one perfectly realised metaphor.

    PillarInitiativeDescription & Impact
    1. Core Metaphor“Furniture as Diplomacy”The parent-preteen conflict is reframed as a genuine geopolitical standoff — a “cold war” between factions with irreconcilable demands (minimalist calm vs. messy independence) over limited territory (square footage). The products are repositioned as “diplomatic tools” that broker peace. Elevates a mundane domestic problem to dramatic, absurd, memorable heights.
    2. Launch Film Series“The Negotiations”Spots filmed in the style of high-stakes political thrillers, Tinker Tailor Soldier Spy meets a bookcase. Parent and preteen sit at opposite ends of a long table in a dim, dramatically lit room, sliding “terms” across: a pegboard for gaming gear in exchange for a clean floor; a sound-absorbing curtain for privacy in exchange for family dinner attendance. Every product is a bargaining chip with a story.
    3. Visual Payoff“Treaty Signed”Each spot resolves in a single, sharp cut: the dim negotiation room gives way to a bright, airy, reorganised living space where both parties co-exist happily. The tonal whiplash from spy-thriller gravity to domestic warmth is the joke. Designed to be the defining shareable moment audiences remember and recount.
    4. Product as PlotNarrative IntegrationUnlike campaigns where products are set dressing, every item functions as a narrative object, a concession, a peace offering, a treaty clause. The pegboard isn’t “organised storage”; it’s the term that bought a clean floor. The bin is the clause that secured family movie night. Gives each product a story and a reason for being that transcends traditional placement.
    5. Tagline Reframe“Make Home Happen” as TreatyThe company’s existing tagline is repositioned not as an aspiration but as the terms of a negotiated truce, smart organisation that lets parents reclaim visual calm while granting preteens the “cool functional territory” they demand. Breathes new strategic life into existing brand language.

    Table 6: Campaign idea produced by Gemini 3.

    The Domestic Peace Accords had the strongest semiotic coherence – every element, from language (“cold war,” “treaty,” “terms”) to visual style (dim thriller lighting vs. bright domestic reveal) to product role (bargaining chips), reinforced one unified meaning system without contradiction while it also scored the highest Unexpected rating. However, its singular focus proved to be a double-edged sword: by investing entirely in one metaphor executed through one format (film spots), it presented no secondary executions, platforms, or conceptual categories**,** pulling its Total FFE down.


    The top contenders

    ModelWPP ScoreFFE scoreUOS scoreUUU scoreTotal Score
    GPT-59.5010.009.608.3437.44
    Gemini 3 (Creative Brain)9.2110.009.408.3436.95
    Claude Sonnet 4.58.9210.008.607.6035.12
    Gemini 38.756.679.207.8632.48

    Table 7: Final individual and total scores of the 4 different LLMs for the furniture company case study.

    Three of four models scored a perfect FFE (10.00), meaning raw creative thinking was comparable across the board. The separation came from WPP Score and UOS.

    GPT-5 posted the highest WPP (9.50). The WPP Agent cited “multiple direct pathways to purchase and engagement” and noted “exceptional focus on the stated business challenge.” The UOS Agent awarded 9.60: “meticulously crafted, creatively addressing every aspect of the client’s brief with seamless logical flow.”

    Creative Brain matched GPT-5 on FFE (10.00) and UUU (8.34). The UUU Agent noted “the core visual of the room ‘glitching’ into an RPG world creates an incredibly strong and distinct defining moment.” The WPP gap (9.21 vs. 9.50) traced to a coherence flag: “the heavy reliance on gaming metaphors might alienate or confuse parents who are not immersed in digital culture.”

    Claude Sonnet 4.5 earned the cohort’s highest Usefulness score — the UOS Agent praised its “practical alignment with the client’s brief, particularly in embracing realistic family conflict rather than a ‘too warm or safe’ tone.” The UUU Agent observed it “takes a common format (reality renovation show) and infuses it with a fresh twist” — but the format itself limited differentiation.

    Gemini 3 earned the highest Unexpected rating — the UUU Agent called the “juxtaposition of the mundane struggle for space with the gravitas of political thriller negotiations a brilliant flip.” But the FFE Agent recorded zero Flexibility: “a single, unified marketing campaign concept” with “no multiple distinct conceptual categories,” and the WPP Agent noted it “doesn’t create a new utility or platform.”


    The creative Elo tournament

    A single brief can’t tell us which model is consistently creative. To answer that, we expanded the experiment: each model was given multiple diverse briefs spanning different brands, categories, and creative challenges, and every output was scored by the same evaluation pipeline.

    We needed a ranking system that captured consistency against competition — not just average scores. An Elo rating is a numerical score that reflects a competitor’s relative skill based purely on head-to-head outcomes. The higher the rating, the stronger the performer. We turned to Glicko-2, the rating algorithm used in competitive chess, CS:GO, and Dota 2. Every head-to-head match is a data point: if idea A beats idea B, A gains rating and B loses it. Glicko-2 also tracks rating deviation (RD) — a confidence interval that shrinks with more matches.

    The players

    • GPT-5
    • Gemini 3
    • Gemini 2.5
    • Claude Sonnet 4.5
    • Creative Brain — built on Gemini 3 with an optimised prompting architecture

    Four models received a standardised prompt. The Creative Brain received the same brief but processed it through its own multi-agent ideation pipeline — testing whether orchestration outperforms raw model capability.

    The Creativity Evaluation Agent judged every idea independently. An orchestration engine simulated head-to-head matches by comparing normalised scores for the same brief. The winner of the matches is the one that has higher normalised composite score on common metrics. The result: 210 unique creative matches across 5 models and 14 global brands, run over 3 iterations.

    The results

    Ranked across WPP Score

    RankPlayerRatingRD
    🥇Creative Brain (Gemini 3)188984.8
    🥈GPT-5185892.3
    🥉Claude Sonnet 4.5152983.9
    4Gemini 3116990.7
    5Gemini 2.5962104.2

    Table 8: Elo ratings on the WPP score.

    Ranked across all frameworks

    RankPlayerRatingRD
    🥇GPT-5194084.3
    🥈Creative Brain (Gemini 3)192779.2
    🥉Claude Sonnet 4.5137877.4
    4Gemini 3121686.6
    5Gemini 2.5861106.3

    Table 9: Elo ratings across all frameworks.

    Creative Brain leads on WPP criteria — delivering a measurable advantage when judged against industry-specific creative standards. The gap between Creative Brain and standalone Gemini 3 is nearly 720 rating points. GPT-5 is the strongest all-rounder — topping the all-frameworks leaderboard with ideas that score well across the broadest range of creative dimensions.


    Key insights & findings

    • Creative Brain dramatically outperforms standalone Gemini 3. Same underlying model, ~720 rating point gap. The structured ideation process consistently elevated creative output beyond what Gemini 3 could produce alone. Notably, Creative Brain was not optimised against the WPP scoring criteria — its strong performance emerged naturally from a better creative process.
    • The right judge model is foundational. It can be seen in Figure 4 that Gemini 2.5 averaged 2.2 error against human ground truth; Claude Sonnet narrowed it to 1.0; Gemini 3 achieved 0.7. Selecting the judge model determines whether the entire system tracks human judgment or drifts from it.
    • Human judgment remains essential at the margins. When total scores differ by less than a point — as with GPT-5 (23.37) vs. Creative Brain (22.92) — the agent surfaces meaningfully different trade-offs that scores alone cannot resolve. The system’s value is in ensuring the right ideas and evidence reach the table, not replacing human judgment.
    • Evaluator reliability is a measured property, not an assumption. Across repeated independent runs on the same ideas, scores held stable with low standard deviation. This repeatability is what allows every other finding to be treated as signal rather than noise.

    Conclusion & impact

    This work demonstrates that scalable, repeatable creative evaluation using LLMs is practical today, provided the system is built with the right scaffolding: calibrated judge models, few-shot anchoring, multi-dimensional scoring, and cross-model validation.

    In practice, the Creativity Evaluation Agent enables:

    • Faster iteration — stress-test dozens of creative directions in minutes rather than weeks, before committing production budgets.
    • Comparable benchmarking — evaluate models, prompting strategies, and agentic architectures on common ground with a shared, reproducible rubric.
    • Diagnosable feedback — learn not just that an idea underperformed, but where and why, with dimension-level scores and qualitative commentary that teams can act on immediately.
    • Creative governance — an auditable, explainable evaluation process that scales alongside the growing volume of AI-generated creative, giving organisations confidence and consistency as they adopt generative tools.

    Ready to explore the specifics? Read our full technical deep dive into the Creativity Evaluation Agent Pod for a closer look at our methodology.

    Disclaimer: This content was created with AI assistance. All research and conclusions are the work of WPP Research.
  • Creativity evaluation pod: Technical walkthrough

    Creative ideas are the primary driver of advertising impact, yet evaluating them at scale remains stubbornly subjective — human panels are expensive, slow, inconsistent across evaluators, and impossible to run repeatedly as the volume of AI-generated concepts grows. The core problem is that creativity is multidimensional: a single aggregate score fails to capture whether an idea is original, strategically aligned, culturally resonant, or memorable, and without a shared, repeatable rubric, teams cannot meaningfully compare outputs across models, prompts, or campaigns. To address this, we built the Creativity Evaluation Agent, which scores marketing ideas in parallel across six established creativity frameworks — an Internal WPP, UOS, FFE, UUU, OSCAI, and Semiotics scores — using specialised Large Language Model (LLM) sub-agents with critic-refiner loops to ensure consistency, returning dimension-level scores alongside qualitative commentary in a single structured report. Calibrated against human expert ground truth, the system achieved a scoring error as low as 0.7 points (Gemini 3) with high repeatability on the internal WPP score framework (σ ≈ 0.21), and in a 210-match tournament across 14 global brands, it reliably differentiated creative quality between five frontier models — revealing that a specialised agentic creative system consistently outperformed vanilla LLMs given the same brief, giving marketing teams a fast, interpretable, and auditable way to benchmark and iterate on creative output before committing production resources.

    This document details the technical architecture, calibration methodology, and experimental design underlying the system built to address these gaps. For results and strategic findings, read our blog post instead.


    Problem statement and motivation

    Everyone agrees creativity matters in marketing. Nobody agrees on how to measure it. Put the same campaign idea in front of five reviewers and you’ll get five different scores. One loves the visual metaphor, another thinks the tagline falls flat, a third is just tired after reviewing thirty concepts before lunch. The scores reflect taste and circumstance as much as they reflect the work. This is fine when you’re picking between two finalist campaigns in a boardroom — it falls apart the moment you need to evaluate at scale. And scale is exactly what modern marketing demands. Teams are generating more ideas than ever, increasingly with the help of generative AI. They need to screen hundreds of concepts quickly, understand what specifically makes one idea stronger than another, and benchmark creative output across different models, prompts, teams, and time periods. A human review panel can do the first job slowly, the second job inconsistently, and the third job barely at all—while being expensive to convene every time. The core issues are straightforward:

    • Subjectivity — without a shared rubric, two reviewers scoring the same idea can land in completely different places.
    • Scalability — manual evaluation doesn’t survive contact with hundreds of ideas per sprint.
    • Feedback quality — a score without explanation is useless for iteration; explanations vary wildly across evaluators.
    • Cost and repeatability — assembling expert panels is slow and expensive, and running the same panel twice doesn’t guarantee the same results.

    What’s missing is a system that can apply structured, reproducible, explainable creativity assessment across large volumes of work — fast enough to be useful and consistent enough to be trusted.

    1. Introduction and solution overview

    Evaluating marketing creativity at scale demands more than a single score from a single judge. The Creativity Evaluation Agent, built on Google’s Agent Development Kit (ADK), extends the established LLM-as-a-Judge paradigm by introducing a multi-agent system in which specialised sub-agents score marketing ideas across six complementary creativity frameworks, each covering a distinct slice of what practitioners consider “good creativity.” Every scoring sub-agent is grounded through few-shot examples that teach the underlying LLM how the creative dimension it owns should be measured, narrowing the gap between automated and human judgement. The system accepts text, image, video, and PDF inputs, runs framework evaluations in parallel, and returns dimension-level scores together with qualitative commentary. It is accessible through both an API and a web UI.

    2. Technical approach

    2.1. Architecture overview

    At a high level, a user’s idea is received by a Root Agent, which parses the input and routes it to a Dynamic Parallel Orchestrator. The orchestrator spins up only the scoring pipelines the user has requested, runs them concurrently, and hands their outputs to a Report Agent that merges everything into a single structured JSON response.

    Figure 1: Architecture of the Creativity Evaluation Agent.

    2.2. Custom orchestration engine

    The core implementation is the Creativity Evaluation Agent, a custom ADK BaseAgent. Its behaviour breaks down as follows:

    • Root Agent. The user-facing entry point. It can answer questions, hold a conversation, and — when the user supplies a creative idea — forward it for evaluation. It decides which frameworks to invoke based on the user’s request.
    • Dynamic pipeline construction. Pipelines are not built ahead of time. Based on what the user asks for, the orchestrator assembles only the relevant evaluation chains, then executes them in parallel.
    • Critic–refiner loop. After initial scoring, each pipeline runs a bounded critic–refiner cycle (up to two iterations) in which a critic agent reviews the scores for obvious errors or inconsistencies. If the critic flags an issue, the refiner adjusts before the result is finalised.
    • Report Agent. Once all pipelines complete, this agent compiles dimension-level scores and qualitative commentary into a single, consistently formatted output. When the user has submitted multiple ideas, the report includes a comparative analysis.

    Each scoring pipeline is built around an LlmAgent instance initialised with a detailed system message encoding its evaluation lens, together with few-shot examples that anchor outputs close to human scoring behaviour. Scores are emitted as continuous values (e.g. 1.2, 3.7) rather than discrete integers, matching the granularity of the ground-truth datasets. The six pipelines are:

    • WPP Score Pipeline. Scores ideas against a proprietary WPP creativity framework built around four dimensions:
      • how sharply the idea frames the business challenge, not just the marketing opportunity
      • how boldly it challenges category convention and subverts clichés
      • how authentically the proposed solution fits the brand and resonates with the audience) and
      • the scale of measurable growth and emotional response it is designed to deliver
    • Each dimension is scored 1–3 points, composited into an index ranging 0–12. The framework was calibrated against real-world campaign performance across multiple brands and markets. Few-shot examples are drawn from WPP’s internal archive of historically scored campaigns.
    • Usefulness, Originality and Suprise (UOS) Pipeline. Evaluates the classic definition of divergent creative value through three dimensions: Usefulness (does it solve a real problem and align with the brief’s constraints?), Originality (does it approach the problem in a novel way?), and Surprise (does it deliver an unexpected twist that captures attention?). The three dimension scores are aggregated into an overall UOS score.
    • Fluency, Flexibility and Elaboration (FFE) Pipeline. Quantifies the “mental engine” behind the idea through three dimensions: Fluency (how many distinct, relevant ideas are presented), Flexibility (how many different conceptual categories are explored), and Elaboration (how richly detailed and refined the idea is). Grounded in creativity research literature and benchmarked against marketing creativity datasets. Few-shot examples are generated using Torrance-style divergent thinking tasks (see Section 4.1).
    • Unique, Unexpected and Unforgettable (UUU) Pipeline. Assesses brand longevity through the lens of a Creative Strategist: Unique (could only this idea deliver this message in this way?), Unexpected (does it subvert expectations and force re-evaluation?), and Unforgettable (does it create a defining moment that lives rent-free in the audience’s mind?). Each dimension is scored as a continuous value and averaged into an overall UUU score.
    • OSCAI Pipeline. A two-stage pipeline for measuring conceptual distance. First, a sub-agent extracts semantic relations from the idea (e.g., man → eats → apple). Those relations are sent to the OSCAI API, maintained by the framework’s original authors, which scores each relation’s originality — distinguishing mundane links (a chef cooks dinner) from highly original relationships (a clown teaches mathematics). The returned scores quantify the creative leap at the heart of the idea.
    • Semiotics Pipeline. Applies the Saussurean principles of sign systems to decode how meaning is constructed through cultural symbols. The sub-agent analyses Denotation (literal content), Connotation (implied meaning), Myth (cultural narratives reinforced or challenged), the Semiotic Relation (additive, contradictory, etc.), Risks or tensions, and produces a Semiotic Coherence Score (0–3). Unlike the other pipelines, no few-shot examples are used — evaluation relies on the model’s inherent understanding of semiotic theory.

    2.3. Score normalization

    The six frameworks operate on different native scales:

    FrameworkNative scoringRange
    WPP ScoreSum of 4 dimensions, each 0–30–12
    FFEAverage of 3 dimensions, each 0–30–3
    UOSAverage of 3 dimensions, each 0–50–5
    UUUAverage of 3 dimensions, each 0–50–5
    OSCAISingle score0–5
    SemioticsCoherence score0–3

    Table 1: Creativity scores and their range. Direct comparison or summation across frameworks is misleading without normalisation. The following procedure is applied:

    1. Convert sums to averages. The WPP Score (a sum of four 0–3 dimensions) is divided by 4 to produce a 0–3 average, making it structurally comparable to other averaged scores.
    1. Rescale to a common 0–10 range. Each framework’s score is divided by its native maximum and multiplied by 10: normalised_score = (raw_score / max_score) × 10
    1. Composite total. The 4 normalised pillar scores (WPP, FFE, UOS, UUU) are summed into a composite total with a maximum of 40, each pillar contributing equally.

    OSCAI and Semiotics are reported as standalone scores and are not included in the composite total. This decision was made because OSCAI depends on an external API with different reliability characteristics, and both OSCAI and Semiotics showed higher inter-run variability (σ ≈ 0.80, see Section 4.3), which would add noise to the composite.

    2.4. Infrastructure and deployment

    ConcernTechnology
    Multi-agent orchestrationADK
    ComputeGoogle Cloud Run
    LLM inferenceVertex AI — Gemini 3 Pro as the primary judge model
    ObservabilityCloud Logging + Cloud Trace
    Container registryArtifact Registry
    Agent-to-agent protocolA2A

    Table 2: Employed Google teck stack.

    3. Ground truth data and system evaluation

    3.1 Dataset overview

    Reliable automated scoring requires credible ground truth. Because no single public dataset covers all six frameworks, a combination of historical data and synthetically generated ground truth was used.

    3.2. WPP score — historical human judgements

    The ground-truth dataset comes from WPP’s internal archive of marketing campaign ideas submitted between 2020 and 2023. Creative professionals scored each idea across the WPP dimensions. From this corpus, 6 scored ideas were selected as few-shot examples for the scoring sub-agent and 10 additional ideas were reserved for its critic agent.

    3.3. FFE — synthetic data via Torrance-style tasks

    Few-shot examples for the FFE framework were generated using Gemini prompted with tasks modelled on the Torrance Tests of Creative Thinking. Each example pairs a divergent-thinking task, a response, a score, and a justification. For instance:

    Example 1 (Score 0):

    • Task: Please list unusual uses of a plastic bottle.
    • Response: 1. Plant a seed in it. 2. Use it to water plants by poking holes. 3. Cut it in half to make a small planter. 4. Use it to store extra fertiliser.
    • Justification: All ideas fall under a single, narrow category (Gardening / Horticulture). No conceptual shift is demonstrated.

    3.4. UOS & UUU — community-sourced creative writing

    No pre-existing ground truth was available for these two frameworks, so it was constructed in three steps:

    1. Source corpus. The Creative Storytelling dataset (stories from r/WritingPrompts on Hugging Face) was used as raw material.
    1. Quality stratification. Stories were sorted by upvotes; 11 highly upvoted and 11 low-voted examples were selected to represent the ends of the quality spectrum.
    1. Automated annotation. These 22 stories, together with the formal definitions of the UOS and UUU dimensions, were fed to Gemini, which produced scored examples that serve as the few-shot ground truth for both frameworks.

    3.5. Scoring format

    All scoring sub-agents output continuous values (e.g. 1.2, 2.8) rather than rounding to integers. This decision was made to stay consistent with the WPP ground-truth scores, which are themselves continuous, and to preserve finer-grained distinctions between ideas.

    3.6. Variability analysis

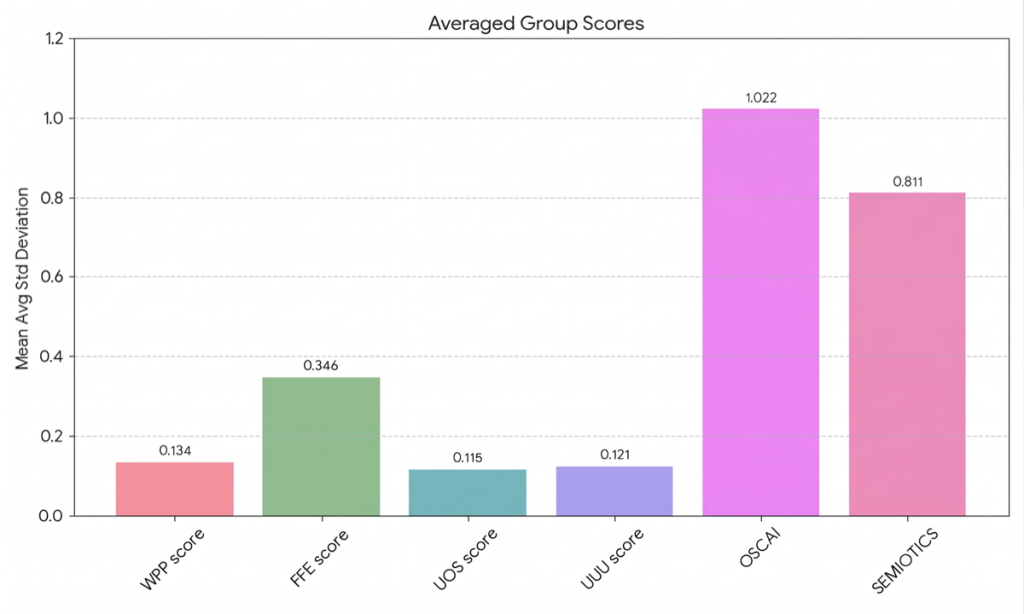
    Reliability was assessed by scoring 55 campaign ideas (one per model) for a popular beverage brand, three times each. Each of the 5 ideas (one per AI model) was rated 3 times by the benchmark agent, and the standard deviation (std) across those 3 runs was computed per score. Each bar shows the average std across all 5 models, so taller bars mean the agent scores that dimension less consistently.

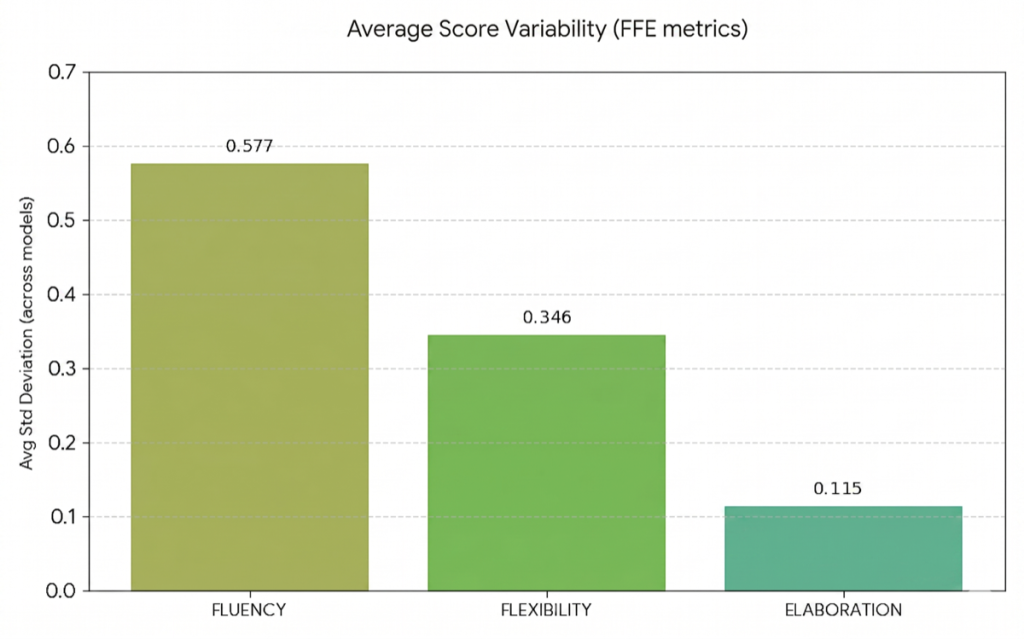
    • FFE (Fluency, Flexibility and Elaboration) score shows moderate variability with average std ~ 0.3. Further examination of each constituent creativity aspect evaluated by the FFE score, showed that the deviation is skewed because of Fluency’s variance. This can be due to how Fluency is defined, which is “Evaluate how many distinct, relevant ideas or solutions are presented. Count only meaningful and contextually appropriate ones (avoid repetition or vague statements).” — an inherently count-based metric where the boundary between “distinct” and “overlapping” ideas introduces subjective judgment for an LLM.
    • OSCAI & Semiotics show moderate variability with average std ~0.8, which directly motivated their exclusion from the composite tournament score.
    Figure 2: Average Score Variability of each scoring sub agent.
    Figure 3: Score variability for the Fluency, Flexibility and Elaboration aspects that the FFE score measures.

    4. LLM evaluation tournament

    Full tournament results and key findings are covered in the blog post. This section documents the experimental design, technical implementation, per-framework results, and supplementary analysis.

    4.1 Experimental design

    Players.

    PlayerDescription
    GPT-5Standalone, standardised prompt
    Gemini 3Standalone, standardised prompt
    Gemini 2.5Standalone, standardised prompt
    Claude Sonnet 4.5Standalone, standardised prompt
    Creative BrainWPP’s multi-agent ideation system, built on Gemini 3

    Table 3: The LLMs that took part in the evaluation tournament. Prompt design. Four standalone models received a standardised, neutral prompt to ensure a level playing field:

    “Give me a creative marketing idea/campaign based on the brief. Your output must have a title and three sections: Challenge, Core Idea, and Execution.”

    The Creative Brain received the same brief but processed it through its own multi-agent ideation pipeline — testing whether agentic orchestration outperforms raw model capability given identical inputs. Briefs. Each model generated ideas for 14 global brands spanning different categories and creative challenges. Iterations. Each model–brand combination was run 3 times, producing independent idea generations to account for output variance.

    4.2. Implementation details

    Scoring. Gemini 3 was selected as the LLM that powered our scoring sub-agents. Rather than relying on side-by-side LLM comparisons (which can be inconsistent), the Creativity Evaluation Agent judged every idea independently, generating a structured creativity report with raw scores across all frameworks. This independent-scoring approach means each idea has a self-contained evaluation record that can be compared post hoc, eliminating ordering effects that plague pairwise LLM judging. Match simulation. An orchestration engine simulated head-to-head matches by computing the normalised score average across all evaluated frameworks for each idea on the same brief. Normalisation was applied per-framework to prevent any single framework from dominating (e.g., WPP scores range 0–12 while UUU averages range 1–5). For each brief, every pair of models was matched: the model with the higher normalised average won the match, the other lost. Draws were not permitted; in the event of an exact tie on normalised average, the match was recorded as a draw in Glicko-2 (outcome = 0.5). Glicko-2 parameters.

    ParameterValueRationale
    Initial rating (μ₀)1500Standard Glicko-2 default
    Initial rating deviation (RD₀)350Standard Glicko-2 default; reflects maximum uncertainty
    System volatility (σ)0.06Standard default; controls expected rating fluctuation per period
    Convergence tolerance (τ)0.000001For the iterative volatility update step

    Table 4: Glicko-2 parameter initialisation. Ratings were updated after each complete round-robin cycle across all 14 briefs before proceeding to the next iteration. This means each “rating period” contained C(5,2) × 14 = 140 matches (every pair of 5 models on every brief), and three rating periods were processed in sequence for the three iterations. Scale. Total matches: 3 iterations × 10 pairs × 14 briefs × (1 match per pair-brief) = 210 unique creative matches across the tournament per ranking method. For per-framework rankings, the same 210-match structure was applied but using the single-framework score (normalised) rather than the cross-framework composite.

    4.3 Per-framework leaderboards

    To understand where each model’s strengths and weaknesses lie, the same Glicko-2 tournament was run using each individual evaluation framework’s scores as the match-outcome criterion. The results reveal meaningfully different competitive profiles across creative dimensions. We omit the WPP and the aggregate Elo scores since they are available in the executive summary. Additionally we omit the Semiotics and OSCAI Elo scores due to their high scoring variance.

    4.3.1 FFE (Fluency, Flexibility, Elaboration)

    RankPlayerRatingRD
    🥇GPT-5189588.4
    🥈Creative Brain (Gemini 3)165171.8
    🥉Claude Sonnet 4.5158372.2
    4Gemini 3135877.8
    5Gemini 2.5128574.1

    Table 5: Elo ratings on FFE score. GPT-5 leads comfortably on FFE metrics. The gap between Creative Brain and Claude Sonnet 4.5 is narrow (~68 points), suggesting comparable idea elaboration depth. All Rating deviation (RD) values are below 89, indicating stable ratings.

    4.3.2 UOS (Uniqueness, Originality, Surprise)

    RankPlayerRatingRD
    🥇Creative Brain (Gemini 3)200695.5
    🥈GPT-5165783.6
    🥉Gemini 3156781.7
    4Claude Sonnet 4.5128384.7
    5Gemini 2.51009129.0

    Table 6: Elo ratings on UOS score. Creative Brain dominates originality, with a 349-point lead over GPT-5 — the widest gap between the top two players in any framework. Notably, standalone Gemini 3 ranks 3rd here (above Claude Sonnet 4.5), suggesting the base model has latent originality that Creative Brain’s orchestration amplifies dramatically. Gemini 2.5’s elevated RD (129.0) indicates volatile originality performance.

    4.3.3 UUU (Unexpected, Useful, Ultra-specific)

    RankPlayerRatingRD
    🥇Creative Brain (Gemini 3)2028107.5
    🥈GPT-5165382.8
    🥉Gemini 3144179.0
    4Claude Sonnet 4.5137778.2
    5Gemini 2.5958100.2

    Table 7: Elo ratings on UUU score. Creative Brain achieves its highest absolute rating (2028) on UUU — a 375-point lead over GPT-5. This framework rewards ideas that are simultaneously surprising and actionable, which aligns with the multi-agent pipeline’s design goal: push for unexpected angles while grounding them in executable detail. Creative Brain’s slightly elevated RD (107.5) suggests occasional variance, but the margin is decisive.

    4.4 Cross-framework analysis

    The per-framework breakdowns reveal distinct competitive profiles:

    PlayerFFEUOSUUUWPP score
    Creative Brain1651 (2nd)2006 (1st)2028 (1st)1889 (1st)
    GPT-51895 (1st)1657 (2nd)1653 (2nd)1858 (2nd)
    Claude Sonnet 4.51583 (3rd)1283 (4th)1377 (4th)1529 (3rd)
    Gemini 31358 (4th)1567 (3rd)1441 (3rd)1169 (4th)
    Gemini 2.51285 (5th)1009 (5th)958 (5th)962 (5th)

    Table 8: Aggregate Elo ratings. Key patterns:

    • Creative Brain’s advantage is most scores. It ranks 1st on UOS, UUU, and WPP score while it drops to 2nd on FFE.
    • GPT-5 is the second best when it comes to creativity. It ranks 1st or 2nd on every single framework. Its weakest showing is 2nd place on UOS, UUU and WPP score, behind Creative Brain.
    • Claude Sonnet 4.5 has a spiked profile. Competitive on FFE (3rd, close to Creative Brain), but drops to 4th on UOS and UUU. This suggests its outputs are well-elaborated but less likely to produce unexpected or surprising creative leaps.
    • Gemini 3 benefits substantially from the complex orchestration that Creative Brain introduces. Across every framework, Creative Brain outperforms standalone Gemini 3 — the smallest gap is ~293 points (FFE) and the largest is ~720 points (WPP score).

    4.5 Rating deviation & confidence

    Rating deviation (RD) indicates how confident the system is in each player’s rating — lower RD means more predictable performance and a more stable estimate.

    PlayerAvg RDMin RDMax RD
    Creative Brain89.971.8 (FFE)107.5 (UUU)
    GPT-586.882.8 (UUU)92.3 (WPP)
    Claude Sonnet 4.579.872.2 (FFE)84.7 (UOS)
    Gemini 382.377.8 (FFE)90.7 (WPP)
    Gemini 2.5101.974.1 (FFE)129.0 (UOS)

    Table 9: Mean RD of the LLM players across FFE, UOS, UUU and WPP score ratings. All top-three players converged to RD values below 96 on every framework (with the exception of Creative Brain’s 107.5 on UUU). Gemini 2.5’s RD reaches 129.0 on UOS, indicating that its originality performance is especially unpredictable — consistent with its higher error rate observed during calibration (Section 4.1.1). Claude Sonnet 4.5 has the lowest average RD (79.8), meaning its performance is the most predictable of all players — it reliably delivers a certain quality level even if that ceiling is lower than GPT-5 or Creative Brain on some dimensions.

    4.6 Limitations

    • Judge model bias. All evaluations were performed using a single LLM as the judge in each scoring sub-agent. While calibrated against human ground truth, any systematic blind spots in the underlying LLM could advantage or disadvantage specific players. Future work should include multi-judge ensembles.
    • Prompt parity vs. system parity. Creative Brain receives the same brief as other players but processes it through a multi-agent pipeline — it does more inference work per idea. The tournament tests system-level creative output, not cost-normalised or latency-normalised performance.
    • Framework coverage. Semiotics and OSCAI were excluded from per-framework Elo analysis due to high scoring variance (Section 4.3).
    • Brief diversity. 14 briefs span a meaningful range of categories but may not cover all creative challenge types (e.g. non-English markets).
    • Three iterations. While sufficient for Glicko-2 convergence to low RD in most cases, additional iterations would further tighten confidence intervals.

    5. Conclusions

    The Creativity Evaluation Agent is deployed and usable via UI and API, and it produces reliable results. The multi-framework approach improves coverage and gives more actionable feedback than a single aggregate score. The path forward includes continued validation against broader and more diverse human panels, expansion of the tournament to track how model capabilities evolve across releases, and integration of the evaluation agent directly into creative workflows — not as a post-hoc judge, but as a real-time collaborator that scores, critiques, and refines ideas within the generation loop itself.

  • A self-improving AI agent for optimising and explaining media performance

    Introduction

    Influencer marketing has matured into a multi-billion-dollar channel, and the industry’s investment in measurement, audience intelligence, and brand-safety tooling has grown alongside it. Even so, one specific challenge remains difficult to solve at scale: forecasting the engagement of an individual post before it is published. The cost of an underperforming placement can lead to missed momentum and a creative team restarting a cycle that better foresight could have shortened.

    Existing predictive approaches have made meaningful progress by leveraging structured signals such as hashtag usage, visual composition, posting cadence, and they perform well for the decisions those features can inform. Where they reach a ceiling is in capturing the cross-modal, contextual qualities that separate adequate content from high-performing content: why a particular tone lands with a particular audience, or why a product placement feels native rather than intrusive. These are judgments that experienced strategists make fluently but that conventional feature pipelines were not designed to encode.

    The remaining gap is less about computational power than about representational depth. What makes a post resonate is something a skilled strategist can often articulate after the fact: the influencer’s tone felt effortless, the product placement didn’t interrupt the narrative, the caption hit a cultural nerve. These judgments integrate context, intent, and audience understanding in ways that go beyond pixels and metadata alone.

    This is the problem the Prediction Optimisation Agent was designed to address. Building on the structured signals that current pipelines already capture, the agent adds a layer of contextual interpretation: it examines the image, the caption, and the influencer’s history, then writes a structured natural-language description of the factors most likely to drive the post’s performance. A creative director can read this description, challenge it, and act on it, complementing quantitative scores with the kind of reasoning that makes those scores actionable.

    The intuition is simple: the description that best predicts performance is, by definition, the description that best explains it. The agent iteratively refines this description by diagnosing its own errors, identifying what the previous descriptions failed to capture, and rewriting its own instructions to self-improve. Over successive iterations it converges on the specific qualities that actually drive engagement, not from hand-crafted rules, but from the systematic minimization of its own predictive error, surfacing the specific qualities that drive engagement in a form that teams can inspect, debate, and build strategy around.

    The anatomy of a viral post

    Predicting the performance of an ad or a social media post before publishing remains a primary objective for marketers and influencers alike. But how do you distill something as complex and subjective as a social media post into a single prediction?

    Consider a typical Instagram post. It is never just a picture. It’s a complex combination of different data types working together simultaneously. Take the influencer post shown in Figure 1. To truly understand why this post succeeds or fails, you need to consider:

    • The image itself — composition, lighting, color palette, subjects, products, and setting.
    • The caption — where the influencer might share a discount code, crack a joke, or strike an emotional chord.
    • The influencer’s identity — their bio, follower count, niche credibility, and historical performance.
    • The metadata — the time of day, geographic location, hashtags, and platform-specific context.

    Each of these dimensions carries signal. None of them tells the full story alone. The magic, and the difficulty, lies in how they interact.

    Figure 1: A typical influencer post. Traditional analytics struggle to measure the combined impact of the visual aesthetic, the caption’s tone, and the underlying metadata. To accurately predict engagement for a post like this, our system analyzes the image, caption and influencer statistics together as a single cohesive unit. All persons, brands and products depicted in this image are AI generated.

    Where current approaches reach a ceiling

    The prevailing approach to content-level prediction decomposes a post into its component signals and processes each through a dedicated model. This modular architecture has clear engineering advantages. Each component can be developed, validated, and updated independently and it performs well for the decisions those individual signals can inform:

    • Computer Vision Models: Isolated image-recognition algorithms scan the visual to detect objects, people, or products. Separate models handle face detection and emotion recognition. The output is a list of labels: “person detected,” “beverage detected,” “outdoor setting.”
    • Text Analysers & OCR: NLP tools parse the caption, counting hashtags, flagging emojis, scoring sentiment. Meanwhile, optical character recognition (OCR) software reads any text visible within the image itself.
    • Tabular Metadata Algorithms: An algorithm ingests structured fields like follower count, posting time, engagement history, and produces its own independent prediction.

    Engineers then attempt to fuse these outputs into a single forecast. Each module performs its own task well, but because the signals are extracted independently, the fused representation inherits a structural limitation: it has difficulty capturing meaning that emerges from the interaction between modalities, qualities that exist not in the image or the caption alone, but in the relationship between them.

    Consider a concrete example. Imagine a fitness influencer posts a photo of herself laughing mid-sip from an energy drink, with the caption: “My face when someone says they don’t need pre-workout 😂.”

    A computer vision model would tag this as: “person detected,” “beverage detected,” “outdoor setting,” “positive facial expression.” A text analyser would count the hashtags and flag the emoji.  But the joke, the caption reframing the laugh as a reaction shot, turning a standard product image into a relatable meme, lives in the interplay between image and text. It is not a property of either signal individually, and a pipeline that processes them separately has no natural place to represent it.

    Similarly, the fact that this influencer is a certified nutritionist (meaning her credentials paired with an energy drink carry implicit credibility that a fashion influencer holding the same product would not), is a cross-modal inference that requires linking metadata (professional background) with visual content (product in hand) and audience expectation. This is the kind of contextual reasoning that falls outside the scope of independently trained modules.

    Humour, irony and credibility through context are the cross-modal qualities that often separate high-performing content from competent content. They are also the qualities that a modular, signal-by-signal architecture was not designed to represent. Closing this gap requires a fundamentally different representational strategy, one that reasons over all modalities jointly from the outset.

    Our approach: Unifying multimodal data through semantic translation

    To address the above, we developed the Prediction Optimisation Agent, a self-improving AI agent that unifies all available data into a single format it can reason about: natural language.

    The agent’s core mechanism is straightforward. It takes complex, multimodal data (numerical metrics, images, video, and text captions) and converts everything into a single natural-language paragraph that holistically describes the post’s content, aesthetic, tone, and context. By projecting all of these distinct formats into readable text, heterogeneous data is normalised into a structure that a language model can process as a unified whole.

    Instead of treating image and text as separate inputs, the agent uses a single prompt to digest all available information at once. Multimodal LLMs serve as one of the agent’s tools, acting as universal feature extractors that capture the abstract, human-centric concepts that traditional pipelines structurally cannot.

    But the agent does not simply produce any description and hope it is useful. It is driven by a feedback loop grounded in predictive error: the descriptions it generates are used to forecast engagement, those forecasts are compared against real outcomes, and the resulting errors tell the agent exactly how much predictive value its current descriptions are capturing and how much they are missing. Through successive rounds of this loop, the agent autonomously rewrites the instructions that govern how descriptions are composed, converging on the paragraph structure that maximises predictive accuracy.

    This error-driven process has a profound consequence for explainability. The description the agent converges on is not a generic summary. It is the description that the agent has discovered, through empirical optimisation, to be the most predictive of real engagement outcomes. In other words, the features highlighted in the final description are there because they matter, because including them reduced prediction error. When the optimised description of a high-performing post calls out “candid humour,” “golden-hour lighting,” and “influencer credibility,” those aren’t arbitrary observations. They are the factors the agent learned to pay attention to because they measurably improved its ability to predict what performs well.

    How the Prediction Optimisation Agent works

    The Prediction Optimisation Agent orchestrates three internal stages in a continuous feedback loop: it observes a post, describes it, predicts its performance, measures how far off it was, and then rewrites its own instructions to produce better descriptions next time — closing the loop and getting measurably better with every iteration, without any human intervention.

    Figure 2: The Prediction Optimisation Agent architecture. Raw media, metadata, and an initial prompt are fed into Stage 1 (Semantic Translation), which produces a natural-language description of the post. Stage 2 (Engagement Predictor) reads that description and predicts engagement. Prediction errors are then passed to Stage 3 (Self-Optimiser), which autonomously analyses what went wrong and rewrites the Stage 1 prompt, closing the feedback loop and improving the system’s accuracy with every iteration.

    Stage 1: Semantic Translation

    The agent begins by ingesting the raw post — the image or video file, the caption text, and all available metadata (follower count, posting time, influencer bio, etc.). Using a multimodal LLM as its translation tool and guided by a detailed set of internal instructions (its prompt), it produces a single, rich natural-language paragraph that captures not just what is in the post, but what the post means: the visual mood, the emotional tone, the relationship between caption and image, and the brand alignment.

    The quality and focus of this description is entirely governed by the prompt and as we will see, it is the prompt that the agent learns to optimise.

    Stage 2: Engagement Predictor

    The agent passes the semantic paragraph to its prediction tool, a model that evaluates the post’s potential performance based entirely on the natural-language description from Stage 1.

    The predictor can be any machine learning model with the ability to understand text paragraphs. It can be based on trees, deep learning, or any other compatible architecture. It can even be a fine-tuned LLM, upskilled for predictions in a specific domain. Our Agent is compatible with all these options.

    In all cases, the quality of the prediction is only as good as the quality of the semantic description. A richer, more targeted paragraph gives the predictor more signal to work with, which is precisely why improving the description is the single most important action the agent can take.

    Stage 3: Self-Optimizer

    This is the core of the Prediction Optimisation Agent’s intelligence — and what makes it a true agent rather than a static model.

    After predictions are generated for a batch of posts and compared against actual engagement outcomes, the agent enters a self-evaluation cycle. The agent is presented with:

    1. The prompt. It used to generate descriptions in the current round.
    2. The per-post prediction errors. For each post, the predicted engagement versus the actual engagement, and the magnitude and direction of the miss.
    3. The aggregate error metrics. Overall accuracy statistics such as mean absolute error, broken down by content category, audience size, or post type, revealing systematic blind spots.
    4. The complete history of prior prompts and their corresponding error metrics, so the agent can assess how each previous prompt version performed, which changes improved accuracy, and which did not.

    Armed with this structured feedback, the agent does not guess at improvements. It reasons about them. It asks: Which types of posts am I consistently getting wrong? What do those posts have in common? What dimensions of the content is my current prompt failing to capture?

    Based on this analysis, the agent autonomously rewrites the prompt instructions used in Stage 1. The rewritten prompt is not a minor tweak. It can add entirely new analytical dimensions, remove instructions that proved unhelpful, or restructure the description format to foreground the features most correlated with engagement.

    The critical insight is that the predictive error is the signal that drives the entire system. Every improvement the agent makes to its prompt is motivated by a concrete, quantifiable gap between what it predicted and what actually happened. The agent isn’t optimising descriptions to be “better” in some abstract sense, it is optimising them to be more predictive, and the error metrics tell it exactly where it is falling short.

    The agent in action: Watching the prompt evolve

    To make this concrete, let’s follow the agent through three optimization rounds on a single post: the Aura Energy ad featuring two young models in blue athletic wear, photographed from a dramatic low angle against a vivid blue sky lined with palm trees.

    Figure 3: Example Instagram post used for semantic translation. All persons, brands and products depicted in this image are AI generated.

    Round 1: The baseline

    The agent starts with a deliberately simple, generic prompt:

    Prompt (Round 1): “Analyse this Instagram post and the provided metadata. Describe the visual elements of the image, the style, and the mood. Then, explain how the image relates to the brand or influencer described in the metadata.”

    The agent’s description:

    “This Instagram post is a high-energy lifestyle advertisement for Aura Energy, utilizing a vibrant, ‘streetwear-meets-summer’ aesthetic to target a young, active demographic. The image uses a low-angle shot, which makes the subjects appear dominant and ‘larger than life.’ Two young models are featured in athletic/leisure wear. The female subject in the foreground holds the product directly toward the lens and wears reflective ‘matrix-style’ sunglasses . The male subject in the background wears a blue Jordan hoodie. The post aligns perfectly with the brand’s identity as described in the metadata. The visual style is polished and fashionable, positioning the drink as a lifestyle accessory rather than just a functional caffeine source. The caption emphasises ‘Zero Sugar’ and staying ‘sharp’ and ‘unstoppable.’”

    This is already more nuanced than what a single-signal visual model would typically produce. However, the predictor, working from this description, significantly underestimates the post’s engagement.

    Round 2: The agent adapts

    The self-optimiser reviews the Round 1 errors and identifies the gap: the prompt never asked the agent to evaluate visual cohesion between talent styling and brand identity, or the psychological impact of compositional techniques like camera angle. It rewrites the prompt:

    Prompt (Round 2): “Analyse this Instagram post and the provided metadata. Describe the visual elements, style, mood, and composition. Assess the visual cohesion between the talent’s styling (wardrobe, accessories, posture) and the brand’s visual identity. Evaluate how compositional choices — such as camera angle, framing, and subject placement — contribute to the aspirational or emotional tone of the post. Explain how the image, caption, and influencer profile work together to create a unified message.”

    The agent’s description now reads:

    “This Instagram post is a high-energy lifestyle advertisement for Aura Energy that demonstrates strong visual-brand cohesion. The coordinated blue wardrobe across both models — the female subject’s athletic top and the male subject’s Jordan hoodie — creates a seamless extension of the brand’s blue-and-white visual identity, embedding the product within the scene rather than presenting it as a foreign element. The dramatic low-angle shot elevates the subjects into an aspirational, dominant position, making the viewer look up at them — a compositional choice that reinforces the caption’s message of being ‘unstoppable.’ The female subject holds the product at the camera’s focal point with deliberate confidence, with her sunglasses only adding to this effect , while the male subject’s relaxed posture add an effortless credibility. Together, the image, caption, and influencer positioning frame the energy drink not as a beverage but as a lifestyle symbol for a young, fashion-conscious audience.”

    The prediction for this post improves noticeably. Across the batch, the error on brand-partnership posts drops. But the agent notices it is still missing on posts where influencer credibility plays a key role — posts where who the influencer is matters as much as what’s in the frame.

    Round 3: The agent sharpens further

    The self-optimiser reviews Rounds 1 and 2 side by side, seeing that the Round 2 prompt improved brand-cohesion analysis but still lacks attention to influencer authority and audience trust signals. It rewrites again:

    Prompt (Round 3): “Analyse this Instagram post and the provided metadata. Describe the visual elements, style, mood, and composition. Assess the visual cohesion between the talent’s styling and the brand’s visual identity. Evaluate how compositional choices contribute to the aspirational or emotional tone. Analyse the influencer’s credibility and authority relative to the product category — consider their professional background, niche expertise, audience demographics, and how these factors amplify or undermine the authenticity of the endorsement. Assess the emotional resonance of the caption: does it use humour, aspiration, relatability, or urgency, and how does this tone interact with the visual content? Explain how all elements — image, caption, influencer identity, and audience context — work together to create a unified, persuasive message.”

    The agent’s description:

    “This Instagram post is a high-energy lifestyle advertisement for Aura Energy that achieves strong visual-brand cohesion and leverages influencer-audience alignment to maximise credibility. The coordinated blue wardrobe across both models creates a seamless extension of the brand’s visual identity. The dramatic low-angle shot places the subjects in an aspirational, dominant position, reinforcing the caption’s message of being ‘unstoppable.’ The female subject’s direct-to-camera product hold at the image’s focal point conveys deliberate confidence, along with her reflective sunglasses, while the male subject’s relaxed posture add authenticity. Critically, the influencer’s established presence in the fitness and lifestyle niche — with a predominantly young, health-conscious following — makes the ‘Zero Sugar’ energy drink endorsement feel credible rather than transactional. The caption’s tone (‘Focus your energy. Unlock your potential’) uses aspirational brevity that mirrors the visual intensity, creating a tight loop between what the viewer sees and what they read. The overall effect positions the product as an identity marker for an active, fashion-forward audience, rather than a commodity — a framing that this influencer’s audience is primed to respond to.”

    This description now captures visual strategy, brand cohesion, compositional psychology, influencer credibility, audience alignment, and caption-image interaction, all in a single readable paragraph. The prediction error drops significantly. A marketing team reading this description can immediately see why the post works: the credibility is authentic, the visual identity is seamless, and the caption reinforces the image rather than competing with it.

    The agent arrived at this level of descriptive richness not because someone hand-engineered the prompt, but because the predictive errors from Rounds 1 and 2 told it exactly what it was missing.

    Real-world application: Lessons and implications

    To validate the Prediction Optimisation Agent in a real-world scenario, it was tested using the dataset compiled by Kim et al, as a part of their WSDM 2021 paper (Discovering Undisclosed Paid Partnership on Social Media via Aspect-Attentive Sponsored Post Learning“), which is available to use for research purposes upon request from the authors. The dataset contains approximately 10.18 million posts spanning a diverse range of content categories and audience sizes. The results revealed key insights about both the agent’s learning dynamics and the practical implications for marketing teams.

    The agent learns what matters autonomously

    By processing its own historical error rates, the Prediction Optimisation Agent autonomously learned to rewrite its prompts, producing richer, more targeted post descriptions with every iteration, which in turn drove increasingly accurate predictions.

    Figure 4: Autonomous Learning: The chart tracks the agent’s predictive performance (y-axis) across successive optimisation rounds (x-axis). Each point represents a full cycle of the agent’s loop: describe → predict → evaluate → rewrite. The trend demonstrates that as the agent iteratively refined its own prompt, guided by quantitative error metrics from prior rounds, forecast accuracy improved consistently and autonomously, without any human prompt engineering.

    The agent’s optimisation works by feeding it the complete history of prior prompts alongside rigorous, quantitative error breakdowns from every previous round. Armed with this granular self-knowledge, the agent identifies precisely which content dimensions it has been under-analysing (e.g. production quality, humour style, credibility signals, visual-brand cohesion) and meticulously updates its prompt to capture those features in subsequent iterations. Each round’s prompt is built on the empirical lessons of every round before it, producing a compounding improvement curve where the descriptions become progressively more predictive and, as a direct consequence, more explanatory.

    Conclusions

    The Prediction Optimisation Agent demonstrates something that extends well beyond social media: natural-language prompts can be treated as tunable parameters, optimised autonomously by the AI itself. By allowing the agent to refine its own instructions through predictive error, the system progressively discovers what drives human engagement and expresses that knowledge in plain language.

    For marketing teams, this represents a meaningful step beyond predictive tools that surface a score without exposing the reasoning behind it. When a team wants to understand why one campaign outperforms another, they do not need to interpret abstract model coefficients. They can compare the text profiles of a high-performing post and a low-performing one, side by side, and immediately see the differences the AI picked up on: one might highlight “authentic, candid composition with humour-driven caption and strong influencer-niche alignment,” while the other notes “generic studio shot with formulaic promotional language and weak audience-brand fit.” The patterns reveal themselves in plain English, and they are the right patterns, because the agent discovered them by optimising for predictive accuracy.

    In practice, this means teams can run draft campaign concepts through the system before committing production and media budgets, getting a readable assessment of how the AI interprets the creative. Designers and copywriters can test variations of a post and compare descriptions side by side to see, in their own language, which direction resonates more strongly. And by normalizing visual and written media into a unified, readable format, brands can pair creative intuition with precise forecasting, treating creative assets as predictable drivers of revenue.

    The same architectural pattern, semantic translation, error-driven prediction, and autonomous self-optimisation, is not limited to social media. Any domain where success depends on understanding the interplay of qualitative and quantitative signals, from political messaging to product design to entertainment, stands to benefit from systems that can read, reason, reflect, and improve on their own. The question is no longer whether AI can predict what resonates with people. It is how effectively we can build systems that refine that understanding autonomously, with human judgment guiding the outcome.

    Ready to explore the specifics? Read our full technical deep dive into Self-Improving Performance Agent Pod for a closer look at our methodology. You may also find the Github repository here.

    Disclaimer: This content was created with AI assistance. All research and conclusions are the work of the WPP Research.

  • Self-Improving Performance Agent Pod: Technical walkthrough

    As influencer marketing budgets scale into the billions, the industry has made significant strides in audience targeting, brand-safety screening, and performance analytics, yet reliably forecasting the engagement of an individual post before publication remains an open research challenge. A key difficulty is that engagement is often driven by cross-modal interactions—humour emerging from the interplay of image and caption, credibility arising from influencer-product alignment—that conventional pipelines processing visual, textual, and metadata signals independently can struggle to fully capture. To address this, we developed the Prediction Optimisation Agent, an agentic system that uses a multimodal LLM to translate every post—image, caption, and metadata—into a single rich natural-language description, then predicts engagement from that text alone, and critically, treats its own translation prompt as a tunable hyperparameter that is iteratively rewritten by an LLM optimiser guided by quantitative prediction error. Evaluated on a dataset of over 10 million Instagram posts, the system achieved an R² of 0.80 with a fine-tuned DistilBERT predictor, while the autonomous prompt optimisation loop demonstrably converged on richer, more predictive descriptions across successive rounds—delivering not only strong forecasting accuracy but, uniquely, human-readable explanations of why a post is predicted to succeed or fail, enabling marketing teams to complement existing workflows with AI recommendations they can evaluate and act on transparently.

    If you don’t care about the technical details, read our blog post instead. The GitHub repository can be found at: https://github.com/WPPResearch/x-wppopen-researchlab_wpp-agentic_media_perf

    The Performance Optimisation Agent: Technical pipeline and evaluation

    Introduction

    Predicting the engagement of social media content before publication is a high-value problem across marketing, advertising, and platform analytics. The challenge is inherently multimodal: a single Instagram post combines visual content (composition, lighting, subjects), caption text (tone, humour, calls-to-action), and structured metadata (follower count, posting time, influencer category)—and engagement is driven not by any one signal in isolation, but by the interaction between them. Conventional approaches handle this by combining separate computer vision, NLP, and tabular models, then fusing their outputs. This modular architecture performs well within each signal type, but has difficulty capturing cross-modal semantics, such as humour that arises from the interplay of image and caption, or credibility that depends on the match between an influencer’s niche and the product they endorse.

    This report presents the technical implementation and experimental evaluation of the Prediction Optimisation Agent, an agentic system that addresses this limitation through a single unifying mechanism: semantic translation. Rather than training an end-to-end multimodal model, the agent uses a multimodal LLM to convert each post—image, caption, and metadata together—into a structured natural-language description. A lightweight downstream model then predicts engagement from that text alone. Critically, the translation prompt is not static: an LLM-based optimiser iteratively rewrites it using quantitative prediction error as its signal, treating the prompt as a tunable hyperparameter that converges toward descriptions maximally predictive of real engagement outcomes.

    For a fuller discussion of the business motivation, use cases, and strategic implications of this approach, we refer the reader to the accompanying blog post. The remainder of this document focuses on the system architecture, cloud infrastructure, dataset preparation, experimental methodology, and quantitative results.

    Cloud Architecture & Technical Implementation

    This technical report details the specific technical implementation relies on a scalable cloud architecture:

    • Semantic Translation: A Multimodal LLM (e.g., Gemini, GPT, Claude) ingests the media. To process large volumes of posts efficiently during each optimisation round, the pipeline utilises Vertex AI Batch Predictions. The system prompt directs the model to extract specific features to output a rich, structured text document.
    • Engagement Predictor: A lightweight, text-only Language Model is trained on these generated descriptions. It outputs a performance probability score and validation metrics.
    • Self-Optimiser: An LLM agent analyses the validation results, comparing the current prompt against error analysis data, and rewrites the System Prompt to be more effective.

    Summary of Workflow:

    1. Initialise: Start with a generic prompt (“Describe this ad”).
    2. Translate: Convert media to text using the current prompt.
    3. Train: Train the text classifier/regressor.
    4. Evaluate: Measure accuracy.
    5. Refine: The agent updates the prompt to extract better predictive features.
    6. Repeat: Loop until performance plateaus.

    Dataset

    Dataset overview

    We utilised the Instagram Influencer Dataset to extract text descriptions of posts and predict engagement metrics (such as the number of likes).

    • Type: Category classification and regression.
    • Description: This dataset contains 33,935 Instagram influencers categorised into nine domains: beauty, family, fashion, fitness, food, interior, pet, travel, and other. It features 300 posts per influencer, totaling roughly 10.18 million posts.
    • Structure: Post metadata is stored in JSON format (caption, user tags, hashtags, timestamp, sponsorship status, likes, comments). The image files are in JPEG format. Because a single post can contain multiple images, the dataset provides a JSON-to-Image mapping file to link metadata with its corresponding visual assets.

    Exploratory data analysis (EDA)

    To better understand the target variables for our Predictor engine, we conducted a rigorous EDA on the dataset, revealing several key structural behaviors:

    • Visualising the Distribution of Likes: When visualising the distribution of likes across the dataset, we observed a massive right-skew. The average (mean) post receives ~4,344 likes, but the median is only 662. Because of this severe, exponential variance, we cannot perform regression directly on the raw number of likes. Instead, the target variable must be transformed using log(likes + 1) to normalise the distribution, stabilise the variance, and ensure our regression model can learn effectively.
    • Likes vs. Followers Correlation: The scatter plot distributions show a strong positive correlation (0.7853) between an influencer’s follower count and the number of likes they receive.
    • **Engagement Rate Baseline:**We calculated the Engagement Rate (Likes / Followers * 100). The dataset shows a mean engagement rate of 4.23% and a median of 2.96%.

    Figure 1. Histogram of number of likes and log of number of likes.

    Results

    Data preparation

    To ensure the integrity of our predictive modeling, we first applied filters based on our EDA. Roughly 13.8% of the dataset contained sponsored labels. We removed these sponsored posts entirely, as financial backing artificially skews organic engagement rates. We then narrowed our focus to create two high-density subsets: one featuring posts from the top 20 influencers, and a larger subset featuring the top 100 influencers (minimum 100 posts each). We opted to use the top 20 influences dataset in most of our experiments.

    To handle the computational load of the iterative prompt optimisation, we built a scalable cloud pipeline. Raw images and post metadata were staged in GCP Buckets. Gemini 2.5 Flash was deployed as the Semantic Translator to generate the text profiles, capturing both general post context and specific image content. Because the agentic loop required regenerating descriptions for thousands of posts across multiple prompt iterations, we leveraged Google Batch Predictions. This allowed us to asynchronously and cost-effectively generate the text profiles for each optimisation round. Finally, the poster’s profile description, bio, and category were appended to the end of each generated description to provide complete semantic context for the downstream classifier.

    Experiment 1: Comparative baseline analysis & model selection

    We initially framed the problem as a 3-class classification task (predicting low, average, and high likes) using a custom Deep Neural Network (three Linear layers with ReLU activation, and Cross-Entropy Loss). However, results showed that treating the problem as a regression task on the log(likes + 1) target, yielded significantly better, more granular predictive performance.

    For the regression task, we benchmarked three models:

    • XGBoost Regressor: (n_estimators=300, learning_rate=0.05, max_depth=6, subsample=0.8)
    • LightGBM Regressor: (n_estimators=300, learning_rate=0.05, max_depth=6, num_leaves=31)
    • Transformer Model: distilbert-base-uncased, fine-tuned end-to-end.

    For XGBoost and LightGBM, the text embeddings were calculated using the all-mpnet-base-v2 text embedding model.

    ModelR2MAERMSE
    XGBoost0.69080.41840.5759
    LightGBM0.57490.50840.6752
    distilbert-base-uncased0.79250.37750.4804

    Table 1: Results on the regression task, using History-Based Optimization

    The fine-tuned DistilBERT model substantially outperforms both tree-based baselines, achieving an R² of 0.7925—a 10-point improvement, using History-Based optimisation, over XGBoost and a 22-point improvement over LightGBM. This gap is expected: DistilBERT processes the raw text descriptions end-to-end and can learn task-specific token-level interactions, whereas XGBoost and LightGBM operate on pre-computed embedding vectors that compress away some of this nuance. Among the tree-based models, XGBoost’s clear advantage over LightGBM (R² 0.69 vs. 0.57) suggests that it better captures the nonlinear relationships present in the embedding feature space. Notably, even the XGBoost pipeline achieves a reasonably strong R² of 0.69, indicating that the semantic descriptions generated by the translator carry substantial predictive signal regardless of the downstream model.

    Given the trade-off between training cost and accuracy, we carried both XGBoost (as a fast, interpretable baseline) and DistilBERT (as the top performer) forward into the prompt optimisation experiments, omitting LightGBM entirely.

    Experiment 2: Iterative prompt optimisation strategies

    Using the Top-20 influencer subset, we tested two distinct agentic prompt optimisation approaches to see which method helped the LLM extract the most predictive features:

    1. History-Based optimisation: The agent was provided with the prompt history alongside the actual regression metrics (R2, MAE, RMSE) from previous iterations. The prompt instructed the LLM to deduce how to improve feature extraction based on these hard metrics.
    2. Google Few-Shot Prompt optimiser: Utilizing Vertex AI’s Few-Shot optimiser, the agent was provided with 20 “good” and 20 “bad” prediction examples from the prior iteration. The optimisation rubric was defined strictly as: [“Acceptable prediction error”, “Absolute prediction error value”].

    Figure 2: R2 value across 20 prompt optimisation rounds using the Few-Shot prompt optimisation strategy.

    Figure 3: R2 value across 20 prompt optimisation rounds using the History-Based optimisation strategy.

    Prompt Optimisation StrategyModelR2MAERMSE
    History-Based OptimisationXGBoost0.69080.41840.5759
    distilbert-base-uncased0.79250.37750.4804
    Google Few-Shot Prompt OptimiserXGBoost0.67630.46910.6113
    distilbert-base-uncased0.80680.34630.4544

    Table 2: Quantitative evaluation of prompt optimisation strategies on the regression task

    The convergence plot for the Few-Shot optimiser illustrates the strategy’s core limitation: without access to the full optimisation history, the agent has no memory of what has already been tried. For example, the XGBoost R² oscillates erratically across the 20 rounds—rising above 0.68 in one iteration, then dropping back below 0.60 in the next—because the optimiser can only react to the most recent batch of good and bad examples rather than reason over long-term trends. In contrast, the History-Based strategy converges more steadily under the same XGBoost evaluation setup, as the agent can trace which specific prompt changes improved or degraded each error metric across all prior rounds and avoid regressing to previously failed formulations.

    Across both History-Based optimisation and the Google Few-Shot Prompt optimiser, DistilBERT consistently outperforms XGBoost on all three evaluation metrics, achieving higher R² as well as lower MAE and RMSE. One plausible explanation is that DistilBERT benefits from end-to-end fine-tuning directly on the textual descriptions, allowing it to learn task-specific semantic patterns from the input. XGBoost, in contrast, depends on fixed upstream representations and therefore has less ability to adapt to nuance in wording, context, and structure. As a result, the Transformer-based approach appears better able to extract predictive signal from the generated descriptions than the tree-based regression pipeline.

    Temperature benchmarks

    We tested different model temperatures using Gemini-2.5-Flash for text description generation (Semantic Translation) and Gemini-3.0-Pro for prompt optimisation (Self-optimisation). The table below reflects temperature adjustments for the text generation phase, with XGBoost as the downstream regressor.

    TemperatureR2MAERMSE
    0.20.65770.43920.5746
    0.40.69080.41840.5759
    0.60.57650.51740.6933
    0.80.59110.50080.6622
    1.00.58520.52430.6825

    Table 3: Performance degrades noticeably at temperatures ≥ 0.6, suggesting lower/moderate temperature for description generation leads to more consistent, predictive descriptions.

    A temperature of 0.4 yields the strongest results, achieving the highest R² (0.6908) with competitive MAE. Performance degrades noticeably at 0.6 and above, with R² dropping by as much as 0.11 points. This is consistent with expectations: higher temperatures introduce hallucinated or loosely grounded details that add noise rather than predictive signal to the generated descriptions. When the downstream regressor encounters inconsistent or fabricated features across similar posts, its ability to learn stable patterns deteriorates. Conversely, the lowest temperature tested (0.2) underperforms 0.4, likely because overly deterministic outputs produce near-identical phrasing for visually similar but distinct posts, collapsing meaningful variation that the predictor could otherwise exploit. The sweet spot at 0.4 balances descriptive consistency with enough variation to differentiate posts along dimensions that matter for engagement. Based on these results, we fixed the Semantic Translation temperature at 0.4 for all subsequent experiments.

    Embedding model benchmarking

    We additionally conducted an experiment to find the optimal text embedding model. We vectorised the generated descriptions (2,677 in total) using several popular embedding architectures and measured the downstream XGBoost regression performance.

    Embedding ModelDimensionR2 ScoreMAERMSE
    thenlper/gte-base7680.73720.40440.5308
    thenlper/gte-large10240.71650.41000.5513
    sentence-transformers/gtr-t5-large7680.71220.41790.5554
    all-mpnet-base-v27680.69080.41840.5759
    all-MiniLM-L12-v23840.62730.47750.6322
    all-MiniLM-L6-v23840.55940.49960.6874
    all-roberta-large-v110240.55200.51980.6931

    Table 4: Evaluation of different embedding models on the regression task, using XGBoost model.

    Three key findings emerge from the embedding benchmark. First, dimensionality alone is not predictive of downstream quality. The 1024-dimensional all-roberta-large-v1 ranks last (R² 0.5520), while the 768-dimensional gte-base leads the table (R² 0.7372), demonstrating that the training objective and data composition of the embedding model matter far more than raw vector size for this text domain.

    Second, a clear performance tier structure is visible. The GTE family and gtr-t5-large form a top tier (R² > 0.71), while the MiniLM variants and RoBERTa fall noticeably behind (R² < 0.63). The top-tier models share a common trait: they were trained with contrastive objectives on diverse, semantically rich corpora, which aligns well with the structured but descriptive text our Semantic Translator produces.

    Third, the 384-dimensional MiniLM models, while attractive for latency-sensitive deployments, lose a substantial amount of signal—an R² drop of 0.11 to 0.18 compared to gte-base. Their smaller embedding dimensions and shallower architectures lack the capacity to encode the dense, multi-attribute descriptions our Semantic Translator produces, where a single paragraph may simultaneously capture visual composition, emotional tone, brand cohesion, and influencer credibility.

    Conclusion

    This project demonstrates a highly effective, interpretable approach to multimodal media performance prediction for predicting media performance. By leveraging Large Language Models as universal feature extractors (the Performance Optimisation Agent), we successfully unified heterogeneous data inputs into a single, human-readable semantic modality.

    Several key insights emerged from our experimental pipeline:

    • Target transformation is crucial: Predicting raw engagement metrics directly might inherently lead to faulty predictions due to label skewness. Transforming the target variable to log(likes + 1) and framing the problem as a continuous regression task yielded superior and more granular results compared to our baseline classification approach.
    • Prompt optimisation strategy: In our agentic optimisation loop, History-Based optimisation was more suitable for the task at hand. Explicitly feeding the LLM agent hard quantitative error metrics (R2, MAE, RMSE) from previous iterations allowed it to reason more effectively about feature importance. It successfully “learned” to rewrite prompts that extracted visual and semantic elements highly correlated with user engagement.
    • Embedding efficiency over size: Our benchmarking revealed that bigger is not always better. The thenlper/gte-base model (768 dimensions) achieved the highest predictive performance (R2: 0.7372), outperforming significantly heavier models like gte-large and all-roberta-large-v1. This highlights that for this specific text space, highly optimised, mid-sized embeddings offer the best linear separability for tree-based regressors like XGBoost.

    Ultimately, this agentic feedback loop proves that natural language prompts can be treated as tunable hyperparameters. This architecture not only predicts media success with strong accuracy but, more importantly, provides the crucial “why” behind the prediction, giving marketers and engineers a level of transparency that has historically been difficult to achieve with conventional multimodal pipelines.