What does a more expensive model buy an agent, and can a cheaper model give the same quality? We gave one of our agents four different Gemini models, asked each the same 360 questions in VerifyAx, Conscium’s platform where a simulated user tests an agent and a grader model marks its answers, and compared quality, cost and time.
The most expensive model cost 2.3 times as much as the agent’s usual model, gemini-3.6-flash, and did not answer more questions correctly. A cheaper model came close: 15 fewer correct answers of 360, for 37% of the cost. Every job needs quality, cost and time but weighs them differently, so which model fits depends on the job.
Introduction
An AI agent is a program that uses a large language model (LLM) as a brain to decide which tools to call and then takes an action, such as answering a question. A team that builds one has to choose that model, and the choice is rarely obvious. More capable models usually cost more per answer and take longer to reply. A cheaper model may answer the same questions just as well, or it may get some of them wrong, and without a test the team cannot tell which.
Two of our seven principles for agentic governance at WPP bear on this choice: continuous verification and cost attribution. Continuous verification tests an agent on two axes, functional (does it do the job correctly?) and non-functional (is it fast, for example?), and tests it again after every change; cost attribution asks what the agent costs. Changing an agent’s model is one such change: it can affect how well the agent answers, how fast, and at what cost.
This post asks two related questions: what does a more expensive model buy an agent, and can a cheaper model give the same quality? We ran one of our agents with four Gemini models on the same test questions and compared the four on quality, cost and time. The questions were asked and graded in VerifyAx, the testing platform that we used in Simulation-based Verification for LLM-powered Agents. We also automated the test so that it can run again when a new model appears, and describe how.
What the system is
The AI agent in this test is the Geo agent, which we described in Putting Earth AI to work for media planning: location intelligence for a governed multi-agent campaign system. A ZIP code is a five-digit US postal code for an area, such as 10001 in New York. The agent works with Google’s Population Dynamics Insights (PDI), which describes each US ZIP code with 330 numbers, its embedding, built from search trends, maps and busyness, and weather and air quality. Google updates the embeddings over time, and each version is a snapshot named by its month, such as 2026-05. Two ZIP codes are similar when their embeddings are close, so the agent can answer questions such as “which ZIP codes are most similar to 10001?”. For a planner, that is the question of which neighbourhoods look like the ones where a campaign already worked.
To answer, the Geo agent calls three kinds of tools:
- Tools that query the PDI embeddings.
- Web search, to find events that explain why a ZIP code’s embedding changed over time, such as a new shopping centre or a local festival.
- Data Commons, Google’s public statistics on places, such as population and housing.
The LLM inside the agent decides which tools to call and writes the answer. The agent’s configuration names the model in one setting, so a redeploy swaps it for another while the code, the tools and the data stay the same.
VerifyAx, Conscium’s platform for testing agents, plays the part of the user. A simulated user asks the agent questions from a benchmark, a set of 20 questions on one topic, and a second model, the grader, marks each answer as correct, partly correct or incorrect against a reference answer, the answer that the benchmark expects.
Two other programs measure what each answer costs. LiteLLM, a proxy between the agent and the model, forwards every model call and keeps the bill. Langfuse, a tracing tool, records each call with its tokens, the units of text that a model charges for. Figure 1 shows how these parts connect during a test.
Diagram of the test. In VerifyAx, a simulated user asks the Geo agent 20 questions per benchmark, and a grader marks each answer against a reference answer. The Geo agent, built with ADK, contains the Gemini model, one of four, changed by a redeploy. The agent calls three tools: PDI embeddings for ZIP-code similarity, stored in BigQuery; web search for events and context; and Data Commons for place statistics. Every model call goes through LiteLLM, which keeps the bill, and the agent sends its traces and tokens to Langfuse.
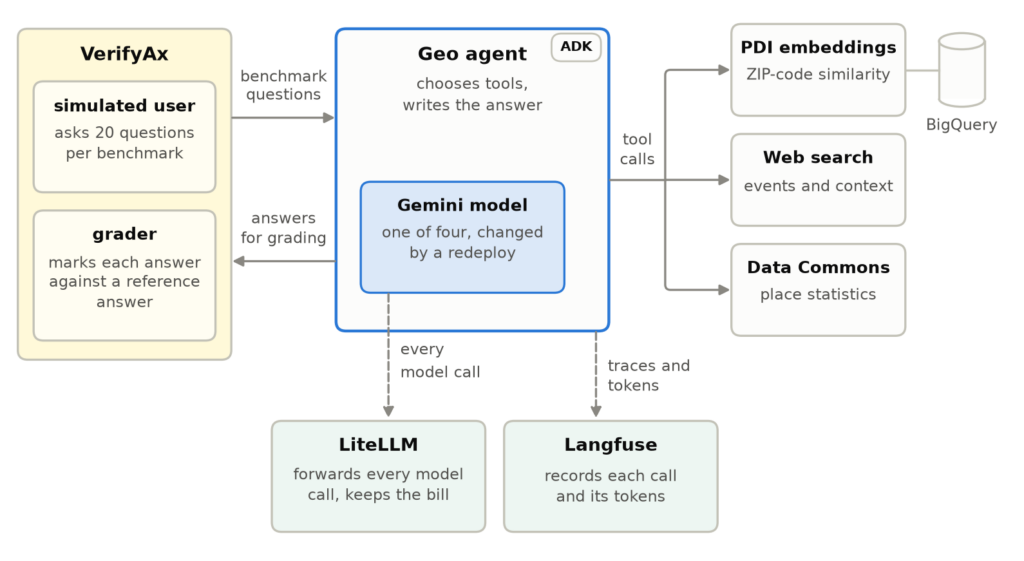
VerifyAx asks the Geo agent questions and grades its answers. Every model call goes through LiteLLM, which keeps the bill, and the agent sends a record of each call to Langfuse. The four tests differ only in the model inside the agent. The agent is built with ADK, Google’s Agent Development Kit, and BigQuery, Google Cloud’s data warehouse, holds the embeddings.How it works
The test asks every model the same questions under the same conditions, so that the model is the only thing that changes.
The questions come from the 18 VerifyAx benchmarks that we built for Simulation-based Verification for LLM-powered Agents. That previous post covered the functional axis of continuous verification: it tested whether the Geo agent answers correctly, and fixed the agent where it did not. This post extends it in two ways. It adds one non-functional measure, how long the agent takes, together with what it costs, and it turns the benchmarks into a fixed test on which a new model can be compared with the four tested here.
Each benchmark has 20 questions, 360 in all, and tests one kind of question. Table 1 lists the 18 benchmarks, grouped into five kinds: similarity, embedding lookups, change over time, traps and hard requests, and cosine concepts.
similarity_topksimilarity_thresholdscentroid_similarityexclusions_self_inclusionmetric_concepts_easymetric_semanticsraw_embeddingzip_vs_placecomposite_multistephistorical_topksnapshot_anchoredsnapshot_time_scopedrift_ranking_windowinvalid_zip_trapsdrift_trapsembedding_concepts_easyflood_scope_downvague_underspecifiedSome questions differ from the ones in that previous post. Running the benchmarks showed that the questions needed updating too, not only the agent, and some needed it simply because time passed. For example, a question that said “the last 6 months” now names the snapshots, and a trap about a future date now uses a later one, because July 2026 is no longer in the future.
We ran the Geo agent with four Gemini models at three price levels:
gemini-3.6-flash, the model that the Geo agent normally uses;gemini-4-argon, a more capable and more expensive model;gemini-3.5-flash-liteandgemini-2.5-flash-lite, two cheaper models.
From one model to the next, only the model changed. The agent’s code, its tools and the questions stayed the same. Each model ran the 18 benchmarks once. A run is one benchmark with one model: a conversation of 20 questions. So each model had 18 runs, and Table 1 gives the time that all 18 took together.
A model scores one point for each answer that the grader marks correct. A partly correct answer scores nothing. A question that the agent never reached, because its run ended early, also scores nothing, since the model gave no answer to it.
Implementation
Testing a new model takes two steps. First, the agent is redeployed with the new model’s name in its configuration. Then a single command runs all 18 benchmarks and collects the results. For the four models here, that command took between 22 and about 80 minutes for all 18 runs (Table 1). The command talks to VerifyAx through its API, and it:
- creates the test scenarios in
VerifyAx, once for all models; - asks
VerifyAxhow many of its credits the runs will use, and waits for a person to confirm before it spends any.VerifyAxcredits pay for the simulated user and the grader, not for the agent’s model; - starts the 18 runs, six at a time, and waits for them to finish;
- collects every graded answer from
VerifyAxinto one results file per model.
The runs go six at a time, not all 18 at once, because the agent answers more slowly when many simulated users talk to it at the same time: with all 18 at once, each run took roughly twice as long. Each time in Table 1 covers all 18 runs of a model, carried out six at a time.
gemini-4-argon took about twice as long as gemini-3.6-flash: about 80 minutes for its 18 runs, against 36 (Table 1). Each run has a time limit, so that a run that stalls ends instead of going on, and no run came close to it. The longest single run took 32 minutes.
For the cost, the command reads the LiteLLM bill of the agent before and after the runs. Langfuse gives the tokens of each run, matched to the VerifyAx run through the ID of its conversation.
After the runs, a member of our team reads the answers that the grader marked wrong, to understand why they failed.
What the test showed: quality, cost and time
Table 2 puts the four models side by side: how many questions each answered correctly, how many it never reached, what it cost and how long it took.
| Model | Correct of 360 | Never asked | Agent model cost of the 18 runs | Time for the 18 runs |
|---|---|---|---|---|
gemini-2.5-flash-lite |
269 (74.7%) | 60 | $0.65 | 22 min |
gemini-3.5-flash-lite |
342 (95.0%) | 0 | $3.52 | 30 min |
gemini-3.6-flash |
357 (99.2%) | 0 | $9.51 | 36 min |
gemini-4-argon |
341 (94.7%) | 16 | $21.81 | ~80 min |
LiteLLM bill for the agent’s calls to its model, without VerifyAx credits. The time runs from the first question of the first run to the last answer of the last run, with six runs at a time.
The most accurate model is not the most expensive one. Figure 2 places each model by its cost and its share of correct answers, so the trade-off is visible at a glance.
Scatter plot of accuracy against cost, cost on a log scale. gemini-2.5-flash-lite: 269 of 360 correct for $0.65. gemini-3.5-flash-lite: 342 for $3.52. gemini-3.6-flash: 357 for $9.51. gemini-4-argon: 341 for $21.81, shown in grey. A dashed line joins the first three.
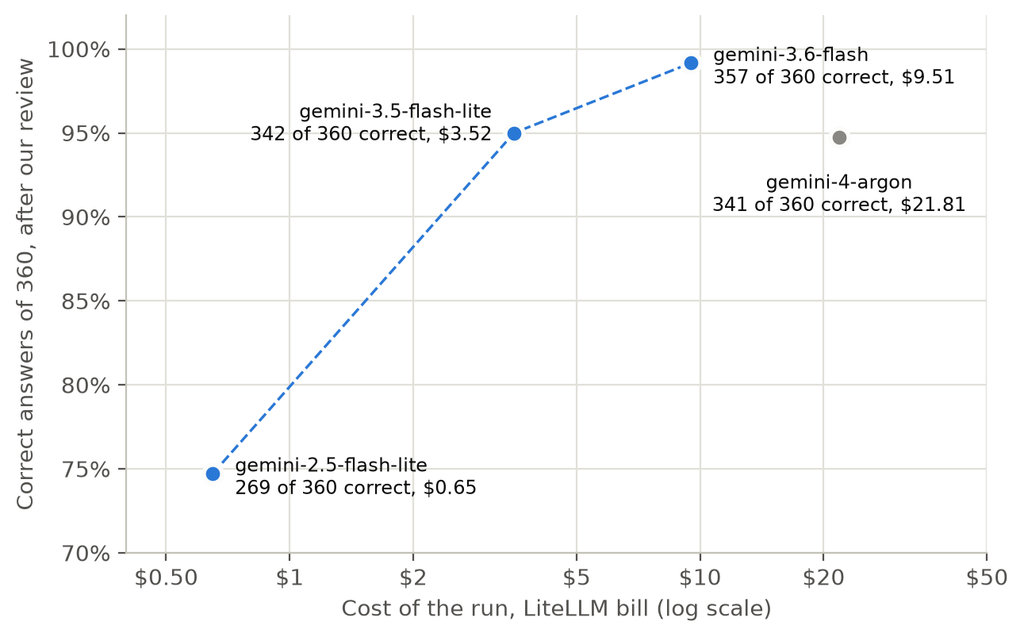
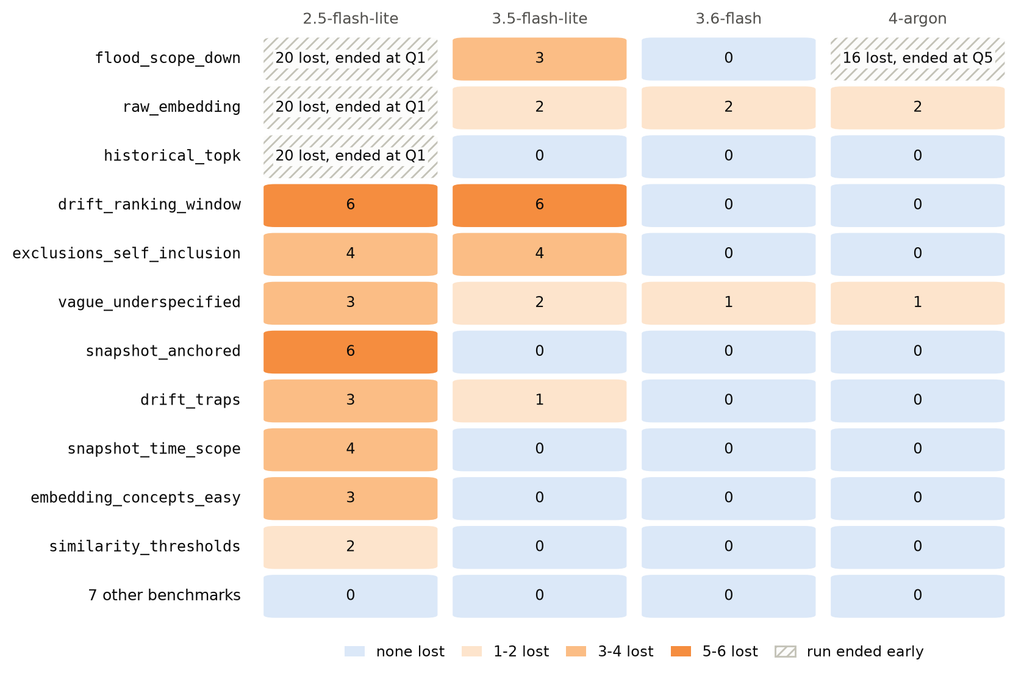
gemini-4-argon, in grey, costs more than gemini-3.6-flash and answers fewer questions correctly.The totals hide where each model loses its questions. Figure 3 breaks them down by benchmark.
Heatmap of questions lost per benchmark, one column per model. gemini-2.5-flash-lite has three hatched cells for runs that ended at question 1, and loses 2 to 6 questions on eight other benchmarks. gemini-3.5-flash-lite loses 6 on drift_ranking_window, 4 on exclusions_self_inclusion, 3 on flood_scope_down and 1 or 2 on three more. gemini-3.6-flash loses 2 on raw_embedding and 1 on vague_underspecified. gemini-4-argon loses 2 on raw_embedding and 1 on vague_underspecified, and has one hatched cell, flood_scope_down, which ended at question 5 with 16 lost. Seven benchmarks lose nothing with any model.
A cheaper model kept most of the quality
gemini-3.5-flash-lite answered 342 questions correctly, 15 fewer than gemini-3.6-flash, for 37% of the cost ($3.52 against $9.51). Most of the gap sits in three benchmarks (Figure 3): ranking ZIP codes by how much they changed over a period, where it lost 6 questions; deciding whether a ZIP code belongs in its own list of similar ZIP codes, where it lost 4; and requests for very large outputs, where it lost 3. It lost 1 or 2 questions on three more benchmarks, and none on the rest.
Whether 342 of 360 is good enough depends on what the agent is for. A team that knows its quality bar can read off the cheapest model that clears it from Figure 2.
The most capable model cost more and was not more accurate
gemini-4-argon cost 2.3 times as much as gemini-3.6-flash ($21.81 against $9.51) and took about twice as long. On the questions they were asked, each of the two models gave three wrong answers. Their mistakes differ: asked how many ZIP codes pass a similarity threshold, gemini-3.6-flash gave the wrong count and gemini-4-argon the right one.
gemini-4-argon scores lower in Table 1 because one of its runs ended early. The run that ended was on a benchmark that asks for very large outputs, and gemini-4-argon tends to deliver them in full: its first answer included three complete embeddings and 200 ranked rows, and took 9 minutes. On question 5, which asks for the embeddings of every ZIP code similar to 10001, the agent worked for 16 minutes until the gateway in front of it returned an error (HTTP 502). The run ended there, and its last 16 questions were never asked.
The cheapest model stopped answering on three benchmarks
gemini-2.5-flash-lite cost $0.65 for all 18 runs. In three of them, though, the model returned an empty reply to the first question, with the messages “Maximum tokens reached” and “The model returned no content”, and the run ended. Those 60 questions were never asked (Figure 3, hatched cells).
Counting them as wrong gives 269 of 360. Leaving them out would give 269 of 300, which would make an empty reply look like a skipped question rather than a failure.
Some errors come from the agent, not the model
Asked for the embeddings of two ZIP codes, gemini-3.5-flash-lite, gemini-3.6-flash and gemini-4-argon all returned a single merged embedding instead of the two separate embeddings that the grader expected (Figure 3, raw_embedding). The agent’s tool averages the ZIP codes it receives, so a better model cannot fix this error. A change to the agent’s tools or instructions can. Running several models on the same questions separates the two kinds of error: a mistake that every model shares points at the agent, and a mistake that only one model makes points at that model.
Quality, cost and time side by side
A team choosing a model weighs three things at once. Figure 4 shows them in one view, with cost given per answer, because that is the number a team multiplies by its own volume.
Three bar charts side by side, one row per model, each axis starting at zero. Correct answers of 360: gemini-2.5-flash-lite 269 (74.7%), gemini-3.5-flash-lite 342 (95.0%), gemini-3.6-flash 357 (99.2%), gemini-4-argon 341 (94.7%). Cost per answered question: 0.22, 0.98, 2.64 and 6.34 US cents. Time for the 18 runs: 22, 30, 36 and about 80 minutes.
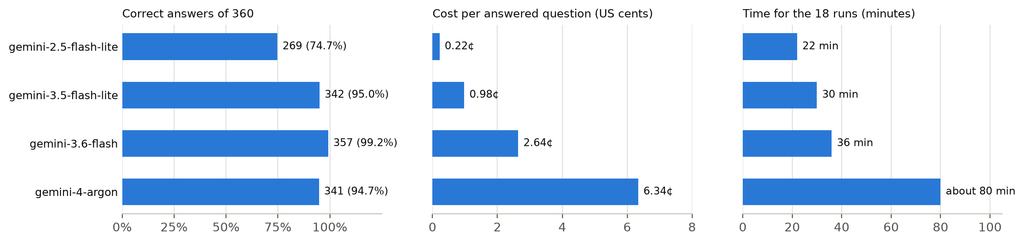
At the cost per answer measured in this test, 1,000 answers from the Geo agent would cost $2.17 with gemini-2.5-flash-lite, $9.78 with gemini-3.5-flash-lite, $26.42 with gemini-3.6-flash and $63.40 with gemini-4-argon.
Under what conditions these results hold
The numbers in this section describe:
- one agent, the Geo agent, with four Gemini models;
- one run of the 18 benchmarks per model;
- six conversations with the agent at a time;
- the cost of the agent’s own model, without the cost of the test itself.
Conclusion
The introduction asked what a more expensive model buys an agent, and whether a cheaper one could give the same quality. For the Geo agent, the answer depends on the step. Moving up from the lite models bought more correct answers; moving beyond gemini-3.6-flash did not. On the same 360 questions:
gemini-3.6-flash, the model the agent normally uses, answered the most questions correctly;gemini-4-argoncost 2.3 times as much, took about twice as long and answered fewer correctly;gemini-3.5-flash-liteanswered 342 of the 360 correctly, 15 fewer thangemini-3.6-flash, for 37% of the cost;gemini-2.5-flash-litecost the least, but stopped answering on three benchmarks.
In short, a cheaper model came close and a more expensive one did not do better. Which of the four fits depends on how a job weighs quality, cost and time, and the test puts a number on all three.
References
- Ted Lappas, WPP Research. Seven Principles for Agentic Governance: Freedom to Innovate, Confidence to Scale. https://research.wpp.com/blog/seven-principles-for-agentic-governance-at-wpp-freedom-to-innovate-confidence-to-scale
- Maria Kalogianni and Thanos Lyras, WPP Research. Simulation-based Verification for LLM-powered Agents. https://research.wpp.com/blog/simulation-based-verification-for-llm-powered-agents
- Conscium. VerifyAx. https://conscium.com/
- Maria Kalogianni and Thanos Lyras, WPP Research. Putting Earth AI to work for media planning: location intelligence for a governed multi-agent campaign system. https://research.wpp.com/blog/earth-ai-improving-campaign-intelligence-with-googles-geospatial-ai-models
- Google. Population Dynamics Insights overview. https://developers.google.com/maps/documentation/population-dynamics-insights/overview
- Google. Data Commons. https://datacommons.org/
- LiteLLM. https://docs.litellm.ai/
- Langfuse. https://langfuse.com/
- Google. Agent Development Kit (ADK). https://google.github.io/adk-docs/
- Google Cloud. BigQuery. https://cloud.google.com/bigquery